Bootstrap confidence intervals estimate uncertainty by repeatedly resampling data while preserving the design that produced the observations. They are especially useful for statistics with skewed or analytically difficult sampling distributions, such as medians, indirect effects, correlations, and some model performance measures. However, bootstrapping is not an automatic cure for a small, biased, dependent, or poorly measured sample.
This guide explains the estimand, resampling unit, interval type, number of replications, diagnostics, psychology-specific examples, software decisions, and reporting details. The goal is a reproducible analysis whose uncertainty statement matches the research question and sampling structure.
Table of Contents
Why bootstrap confidence intervals in your psychology dissertation?
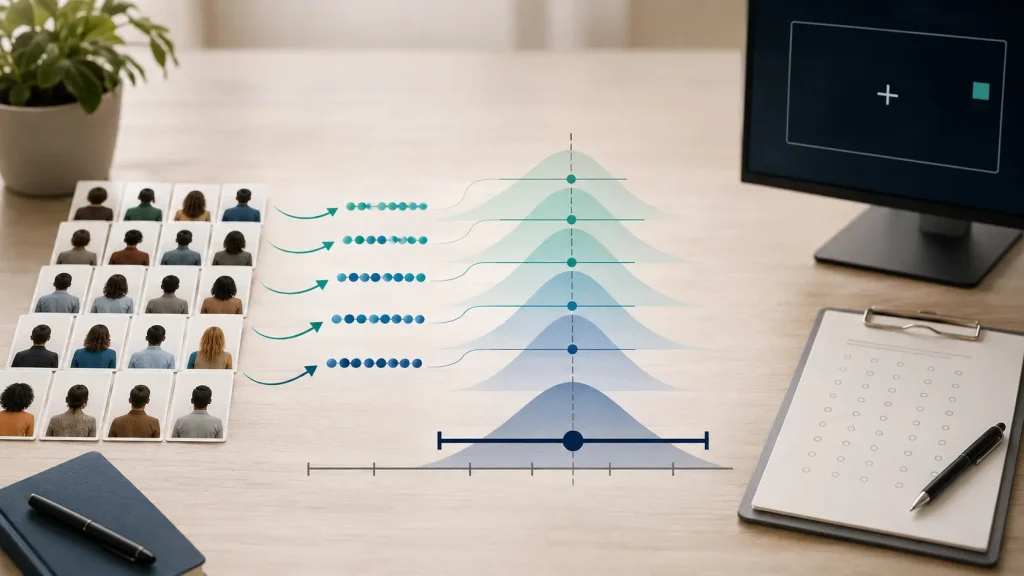
A confidence interval describes the range of parameter values compatible with an estimate and its sampling uncertainty under a stated procedure. A bootstrap interval approximates that uncertainty by treating the observed sample as an empirical stand-in for the population, drawing many resamples with replacement, recalculating the statistic, and using the resulting distribution.
Bradley Efron’s foundational 1979 bootstrap paper introduced this general resampling approach through examples including variance estimation for a sample median. The logic is powerful because the same framework can address many estimators for which a simple standard-error formula is unavailable or unreliable.
The interval still answers a specific question. An interval for a median difference does not estimate a mean difference. An interval for a correlation does not show that one variable causes another. An interval for an indirect effect quantifies uncertainty in the fitted mediation model, not certainty about a psychological mechanism. Define the target parameter before choosing the method.
How the bootstrap workflow operates
Suppose a dissertation contains data from 180 independently sampled participants. A nonparametric case bootstrap draws 180 rows with replacement. Some participants appear more than once and others do not appear in a given resample. The researcher calculates the target statistic, stores it, and repeats the process many times.
- Specify the population, estimand, analysis model, and independent sampling unit.
- Calculate the statistic from the original data.
- Draw one bootstrap resample using a procedure that preserves pairing, clustering, and other dependencies.
- Fit the complete planned analysis to that resample.
- Store the target estimate and record warnings or failures.
- Repeat the resampling and fitting procedure a prespecified number of times.
- Construct the selected interval and compare it with suitable alternatives or sensitivity analyses.
The resampled estimates approximate a sampling distribution conditional on the observed data and resampling scheme. They are not thousands of new participants, and they do not add information absent from the original study. The effective evidence still comes from the original cases, measures, and design.
| Decision | Question to answer | Evidence to report |
|---|---|---|
| Estimand | Which population quantity is being estimated? | Statistic, scale, direction, and model |
| Resampling unit | Which observations are independent? | Cases, pairs, clusters, or model residuals |
| Interval type | How are endpoints obtained? | Percentile, basic, studentized, BCa, or justified alternative |
| Replications | Is Monte Carlo error acceptably small? | Number of successful resamples and seed |
| Failures | Did models fail to converge or estimates become undefined? | Counts, causes, and handling rules |
When bootstrapping is useful in psychology
Bootstrapping can help when the statistic is nonlinear, bounded, skewed, or otherwise difficult to handle with a normal approximation. Common dissertation applications include a median, a difference in medians, a correlation, an effect-size measure, a product of regression paths, a reliability coefficient, or a prediction metric. The method must be supported for the estimator and design.
For mediation, the indirect effect is commonly represented by a product of paths. Its sampling distribution can be asymmetric. The Arizona State University record for MacKinnon, Lockwood, and Williams’ simulation study explains why normal-theory limits can be imbalanced and evaluates resampling alternatives. A bootstrap interval can improve inference for the indirect effect, but it cannot correct weak temporal ordering or uncontrolled confounding. The dedicated psychology dissertation mediation-analysis guide covers those design requirements.
Bootstrapping is also useful for an effect size when an analytic interval is difficult to obtain. The statistic should still be selected for its substantive meaning rather than because software can resample it. Consult the psychology dissertation effect-size guide when choosing the effect metric and interpretation.
Choose the correct resampling unit
The central practical rule is to resample independent units. Ordinary row resampling is suitable only when rows represent independent sampling units and the complete analysis can be applied to each resample. If observations are paired, repeated, nested, weighted, stratified, or collected through a complex design, a different scheme may be required.
Independent participants
For a simple cross-sectional sample with one row per independently recruited participant, resample whole participant rows. Keep all variables on a row together. Resampling predictor and outcome columns separately would destroy their association and estimate the wrong sampling process.
Paired and repeated measurements
For a pretest-posttest study, resample participants while keeping each participant’s paired scores together. If every participant contributes many trials or occasions, do not treat those observations as independent people. The scheme may require participant-level resampling, a multilevel bootstrap, or a model-based procedure that preserves within-person dependence.
Students within classes, clinics, or families
If the primary sampling units are schools, therapy groups, clinics, or families, case resampling can understate uncertainty by breaking cluster dependence. Francis Huang’s simulation study of cluster bootstrapping evaluates resampling for nested educational and psychological data with few clusters. The design question is not solved by selecting a bootstrap menu option. State which level was sampled and why it represents independent replication.
When the substantive model is multilevel, compare the resampling approach with a suitable model-based analysis. The psychology dissertation multilevel-modelling guide explains clustering, random effects, and level-specific interpretation.
Strata, weights, and complex samples
A stratified or multistage sample should be resampled in a way that reflects its selection process. Survey weights may need replicate-weight or design-based methods rather than a generic case bootstrap. If the design cannot be represented faithfully, consult a survey statistician and describe the limitation instead of presenting an apparently precise but mismatched interval.
| Psychology data structure | Likely resampling unit | Main risk if ignored |
|---|---|---|
| One row per independent participant | Complete participant row | Associations destroyed if variables are sampled separately |
| Pretest and posttest per participant | Participant with both scores | Pairing lost |
| Many trials per participant | Participant or justified hierarchical scheme | Pseudoreplication |
| Students nested in schools | School cluster, sometimes with a multilevel procedure | Standard errors too small |
| Stratified probability sample | Design-consistent replicate | Selection process misrepresented |
Choose an interval type deliberately
There is no universally best bootstrap interval. Performance depends on the statistic, sample size, skewness, discreteness, dependence, and model. Software labels also vary, so report the full method rather than writing only “bootstrapped CI”.
Percentile interval
A two-sided 95% percentile interval uses the 2.5th and 97.5th percentiles of the bootstrap estimates. It is intuitive and transformation-respecting, but it can have poor coverage when the bootstrap distribution is biased or the sample is small. Simplicity does not make it automatically defensible.
Basic interval
The basic interval reflects bootstrap quantiles around the original estimate. It corrects the direction of estimated error in a different way from the percentile interval. Its interpretation and transformation behaviour differ, so do not switch between the two merely because one excludes a null value.
Studentized interval
A studentized interval uses a bootstrap distribution of an estimate divided by an estimated standard error. It can offer stronger theoretical performance but may require nested resampling or a reliable standard-error estimate within each replicate. That computational and modelling burden should be acknowledged.
Bias-corrected and accelerated interval
The BCa interval adjusts for estimated median bias and acceleration related to how the statistic changes when observations are removed. It is often useful, but it is not magic. With discrete statistics, highly unstable estimates, very small samples, or influential observations, its adjustments can behave poorly.
Tim Hesterberg’s open review of bootstrap practice warns that a common percentile interval can under-cover in small samples and discusses when resampling methods fail. The correct response is to examine the estimator and data-generating structure, not to claim that every bootstrap interval is distribution-free or assumption-free.
The current R boot package manual documents normal, basic, studentized, percentile, and adjusted percentile intervals. If using R, record the package version, function, arguments, statistic function, resampling type, and any model-fitting warnings.
Assumptions and limitations
The bootstrap substitutes an empirical distribution for the unknown population distribution. That approximation requires the observed sample to contain credible information about the relevant population and tails. Severe selection bias, unmeasured subgroups, restricted ranges, or rare events absent from the sample cannot be repaired through resampling.
Very small samples contain few distinct values and may yield unstable or misleading intervals. A bootstrap does not create genuine sample diversity. If the statistic is undefined in many resamples, such as a correlation when a resampled variable has no variation, the failure rate is itself diagnostic.
Model misspecification also remains. Resampling a regression with the wrong functional form reproduces that wrong form many times. Missing-data bias is not removed by bootstrapping complete cases. Plan the missing-data analysis first, using the psychology dissertation missing-data guide, and then apply a resampling method compatible with it.
- Do not claim that bootstrapping removes all distributional assumptions.
- Do not use it as a substitute for adequate recruitment or representative sampling.
- Do not ignore dependence, clustering, survey design, or repeated measurements.
- Do not discard failed resamples silently.
- Do not choose the interval type after comparing which result is significant.
Set replications and reproducibility controls
The number of replications controls Monte Carlo error from the resampling algorithm, not sampling error in the original study. More replications make simulated quantiles more stable, but they cannot rescue an unsuitable sample or resampling scheme. There is no single count that is sufficient for every statistic and confidence level.
Use enough replications to make the reported endpoints stable to a practically negligible degree. Check stability by rerunning the analysis with a different seed or a larger number of replications. If endpoint changes could alter the substantive conclusion, increase the computational effort and report the sensitivity.
Set and report a random seed when the software permits reproducibility. Also report the software and version, package or procedure, replication count requested, replication count successfully used, confidence level, interval type, resampling unit, and convergence rules. Retain code or syntax in an appendix or approved repository without exposing confidential data.
Worked psychology example
Imagine a dissertation examining whether weekly sleep disruption is associated with attentional lapses among 160 university students. The primary estimand is Spearman’s rank correlation because the lapse count is strongly skewed and contains several high observations. The student plans a two-sided 95% BCa interval and resamples complete participant rows.
The observed correlation is .31. After 10,000 requested replications, 9,998 estimates are usable and the BCa interval is [.16, .44]. This result indicates a positive association of uncertain magnitude in the sampled population. It does not show that sleep disruption causes lapses, and it does not justify a precise prediction for an individual student.
A sensitivity analysis compares the BCa result with a percentile interval and an analytic interval suitable for the coefficient. The endpoints differ modestly but the substantive conclusion is unchanged. The dissertation explains why the participant is the independent resampling unit, names the two failed replicates, reports the seed and software version, and discusses the convenience sample as a generalisability limitation.
If the same data came from students nested in 12 classes, row resampling would no longer match the design. A cluster or multilevel approach would be needed, and 12 clusters may provide weak information for cluster-level uncertainty. That design issue is more important than increasing the replication count from 10,000 to 100,000.
| Report element | Example | Why it matters |
|---|---|---|
| Estimand | Spearman correlation between weekly disruption and lapse count | Defines the target quantity |
| Estimate | rho = .31 | Shows magnitude and direction |
| Interval | 95% BCa CI [.16, .44] | Communicates uncertainty and method |
| Resampling unit | Complete participant row | Preserves association and independence |
| Computation | 10,000 requested; 9,998 usable; seed reported | Supports reproducibility |
| Interpretation | Positive association, not causal proof | Prevents overclaiming |
Software workflow without black-box reporting
In R, define a function that receives the data and resampled indices, fits the planned analysis, and returns the target statistic. Test it on the original data before running thousands of replicates. Inspect the bootstrap object, distribution, warnings, extreme values, and interval calculation.
SPSS, jamovi, Stata, SAS, Mplus, and other packages offer bootstrap options for selected procedures. Their defaults may differ in interval type, resampling unit, missing-data treatment, random-seed control, and handling of failed models. Verify the manual for the specific version. Do not assume a check box implements the method required for nested, longitudinal, imputed, or weighted data.
The APA quantitative reporting standards provide a broader framework for transparent reporting of design, analysis, and results. A dissertation should give enough detail for a knowledgeable reader to understand what was resampled, reproduce the calculation, and evaluate whether the interval supports the stated claim.
Common bootstrap mistakes
- Writing “bootstrap was used because the sample was small” without assessing whether the sample represents the population.
- Resampling individual trials when participants are the independent units.
- Separately resampling variables that must remain paired.
- Reporting only a confidence interval without the point estimate or interval type.
- Treating an interval that excludes zero as proof of practical importance or causality.
- Selecting BCa, percentile, or another method according to which produces the preferred conclusion.
- Failing to disclose nonconvergent, singular, infinite, or undefined replicate estimates.
- Using more replications to conceal instability in the original data.
- Ignoring missingness, weights, strata, clusters, and repeated measurements.
- Omitting the seed, software version, procedure, and successful replication count.
Frequently asked questions
Does bootstrapping fix a small sample?
No. It can approximate uncertainty from the observed empirical distribution, but a very small sample contains limited information about the population and tails. Recruitment, design, and sensitivity checks remain essential.
How many bootstrap replications should I use?
Use enough for stable endpoints at the chosen confidence level and statistic. Report the requested and successful counts, test endpoint stability, and avoid presenting a universal number as sufficient for every analysis.
Should I report percentile or BCa intervals?
Choose using methodological justification, estimator behaviour, software support, and sensitivity evidence. BCa adjusts for estimated bias and acceleration, while percentile intervals are simpler but can perform poorly in some settings.
Can I bootstrap a correlation?
Yes, when resampling preserves complete paired observations and the method suits the coefficient. Report the coefficient, interval type, resampling unit, failures, and a noncausal interpretation.
Can I bootstrap multiply imputed data?
Potentially, but the order and combination of imputation and bootstrapping require a validated procedure. A generic bootstrap applied to one completed data set ignores imputation uncertainty.
What if some bootstrap models do not converge?
Investigate the cause, quantify failures, and check whether excluding them changes the distribution. Frequent failures may show model or data instability and should not be hidden.
Does a bootstrap interval prove an effect is important?
No. Statistical compatibility does not determine psychological importance. Interpret the estimate and interval against theory, measurement precision, practical thresholds, and the study design.
Conclusion
Psychology dissertation bootstrap confidence intervals are most defensible when the estimand, independent unit, resampling scheme, interval type, replication count, and failure rules are specified before results are inspected. Resample the design rather than just the rows, examine the bootstrap distribution, test computational stability, and report uncertainty without turning association into causation.
If you need dissertation support, choose ethical tutoring that helps you understand, reproduce, and defend your own analysis. Keep responsibility for the design, code, interval choice, diagnostics, and interpretation, protect participant information, and follow your institution’s rules on permitted assistance.