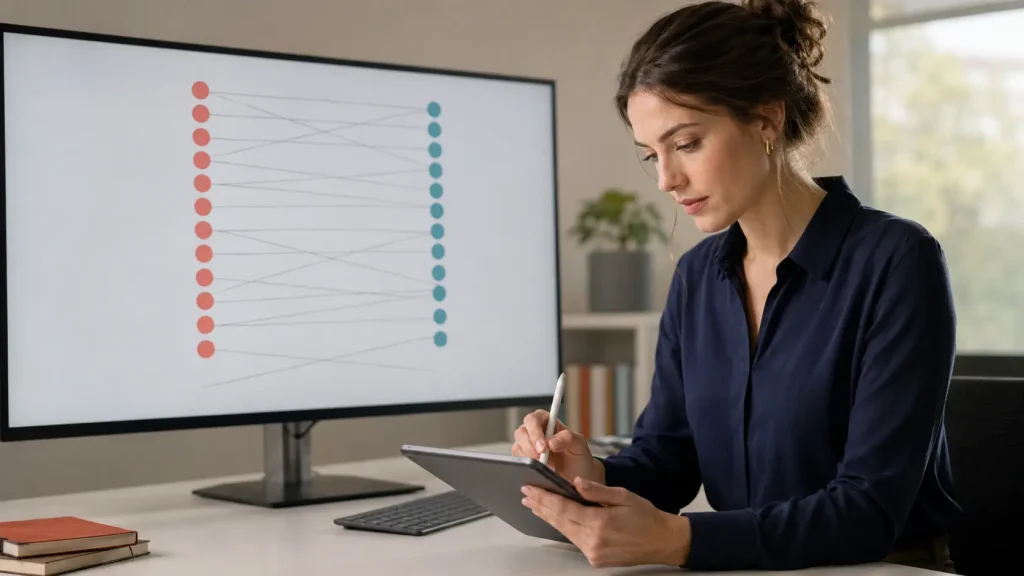
Psychology dissertation optimal pair matching creates treated-control pairs by minimising total distance across the matched sample rather than accepting pairs one at a time.
This distinction matters in observational psychology research. A greedy algorithm can use an excellent control early and leave a later participant with a poor match. Optimal pair matching considers all requested pairs together, seeking a globally efficient assignment under the chosen distance and restrictions.
The method does not create randomisation or remove unmeasured confounding. Its purpose is to improve comparability on measured pre-exposure characteristics before outcomes are analysed. This guide explains when it fits, how to specify it, which diagnostics matter, and how to report it without overstating causal certainty.
Table of Contents
What optimal pair matching means in Psychology
Imagine a dissertation comparing students who voluntarily joined an eight-week stress-management programme with students who did not. Programme participants may begin with different stress, sleep, help-seeking history, academic workload, age, and prior counselling. Directly comparing later wellbeing scores could mix programme effects with these baseline differences.
Pair matching links each focal participant, usually an exposed participant, to one or more comparison participants who are close on a selected distance. The official MatchIt optimal pair matching documentation defines optimality as making the sum of absolute pairwise distances in the matched sample as small as possible.
The word optimal is therefore narrow. It describes the solution to a specified assignment problem. It does not mean that the covariates are sufficient, the distance is correctly chosen, overlap is adequate, balance is automatically good, or the resulting estimate is unbiased.
A small assignment example
Suppose three programme participants each have several possible controls. The individually closest control for the first participant may be the only acceptable control for the third. Greedy nearest-neighbour matching might take that control immediately. Optimal pair matching can assign the first participant a slightly less close control so the third avoids a very poor match. The total distance across all pairs becomes smaller.
This global view removes the need to choose a matching order. It can also reduce the risk of an extreme pair produced because good controls were consumed earlier. However, optimal and greedy matching frequently select similar samples, so the algorithm must earn its place through diagnostics rather than its name.
| Feature | Greedy nearest neighbour | Optimal pair matching |
|---|---|---|
| Assignment process | Selects pairs sequentially | Considers requested pairs jointly |
| Matching order | Can affect the result without replacement | No focal-unit order is required |
| Objective | Best available match at each step | Smallest total absolute pair distance |
| Computation | Usually faster and lighter | Requires a larger distance problem |
| Balance guarantee | None | None |
When psychology dissertation optimal pair matching fits
The method is suitable when a dissertation has a binary exposure, a credible pool of comparison participants, sufficient baseline overlap, and a clear reason to retain a pair-matched design. It is especially relevant when matching without replacement makes order sensitivity a concern.
Potential psychology applications include comparing users and non-users of a counselling service, participants who chose online or in-person therapy, schools that adopted a wellbeing intervention, caregivers who selected different support programmes, or employees who joined optional resilience training.
The exposure must occur after all matching covariates. Do not match on programme adherence, follow-up attendance, post-treatment symptoms, mediator scores, or later attrition. Such variables can be consequences of exposure, and conditioning on them may block part of an effect or introduce bias.
When another design is more appropriate
Optimal pair matching is a poor solution when exposure groups have little common support. No optimisation algorithm can manufacture comparable controls where none exist. Consider restricting the target population, changing the estimand, using a different data source, or concluding that the available data cannot identify the intended effect.
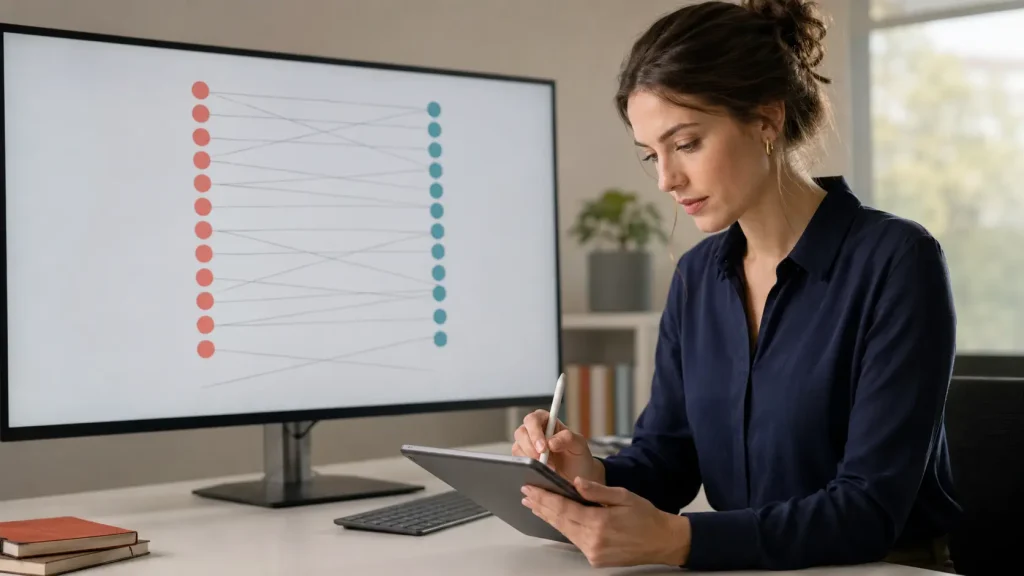
It may also be impractical with very large samples because constructing and optimising a full distance matrix can be computationally demanding. The MatchIt matching-methods vignette notes that nearest-neighbour matching avoids computing the full matrix and can be more applicable to large datasets.
If the goal is to retain most participants through variable-size subclasses, optimal full matching has a different structure. If the goal is to select the largest subset that meets explicit balance constraints, cardinality matching targets a different optimisation problem. Keep these search intents and estimands separate.
Define the causal question before matching
Write the target trial you wish the observational study could emulate. Define eligibility, exposure strategies, assignment time, follow-up, outcome, and causal contrast. This exposes temporal mistakes before software makes them difficult to see.
The average treatment effect in treated participants asks what the exposed group would have experienced under the comparison condition. This is the usual target for pair matching that retains focal participants and selects controls. An average treatment effect for the full eligible population may require a different matching structure or weighting strategy.
For the stress-programme example, time zero might be programme enrolment. Baseline stress, sleep, study load, and earlier counselling must be measured before enrolment. The outcome might be a validated wellbeing score eight weeks later. Both groups need comparable eligibility and follow-up definitions.
Select covariates using subject knowledge
Prioritise pre-exposure common causes of programme participation and outcome, along with strong outcome predictors. A directed acyclic graph can help distinguish confounders from mediators and colliders. Do not choose covariates only because they are statistically significant in the current dataset.
In the example, plausible covariates could include baseline stress, prior mental health service use, age, study level, caring responsibilities, disability accommodations, workload, sleep quality, and financial strain. Site or delivery pathway may require exact agreement if participants at different sites faced different access rules.
Do not include many redundant measurements of the same construct without a plan. High-dimensional matching can make all participants appear distant. Select theoretically justified scores, inspect collinearity, and prespecify nonlinear terms or interactions that are likely to predict outcomes.
Choose the distance separately from the algorithm
Optimal pair matching determines how assignments are made. It still needs a distance that defines closeness. A propensity-score distance, Mahalanobis distance, prognostic score, or user-supplied distance matrix leads to a different optimisation problem and potentially different pairs.
A propensity score estimates the probability of exposure given measured baseline covariates. Matching on its logit can reduce a multivariable profile to one dimension. Model specification still matters, and discrimination is not the goal. The final criterion is covariate balance, not how accurately exposure was predicted.
Mahalanobis matching measures multivariate closeness after accounting for scale and correlation. It can be useful for a modest set of continuous or ordinal prognostic measures. A hybrid design can minimise Mahalanobis distance within a propensity-score caliper.
Use exact restrictions and calipers deliberately
Exact matching can prevent pairs from crossing a substantively essential category, such as research site, broad diagnostic pathway, or programme eligibility band. A caliper prohibits pairs whose distance exceeds a threshold. Both restrictions change the feasible assignment problem.
Restrictions protect against forced matches, but they may leave focal participants unmatched. Report the number excluded and compare retained participants with the original target group. Exclusion can improve internal comparability while narrowing generalisability.
Set calipers and exact variables before inspecting treatment-effect results. If the design is revised, record the balance or overlap reason. Do not change restrictions until the outcome becomes statistically significant.
| Design choice | Question to answer | Evidence to report |
|---|---|---|
| Estimand | Whose effect is being estimated? | ATT, ATC, or another clearly defined target |
| Distance | What makes two participants close? | Model, covariates, transformations, and scale |
| Exact restriction | Which categories must agree? | Variables and substantive rationale |
| Caliper | How distant is unacceptable? | Threshold, scale, and exclusions |
| Ratio | How many controls per focal participant? | Requested and achieved ratios |
| Tolerance | How closely was the optimum solved? | Software setting and convergence information |
Understand ratio, replacement, and feasibility
One-to-one matching is straightforward and often yields close pairs. Adding controls can improve precision when many comparable controls exist, but later controls may be less similar. The chosen ratio should reflect overlap, balance, estimand, and effective information rather than a desire to keep every record.
Optimal pair matching is usually discussed without replacement, because global allocation is most relevant when controls cannot be reused. If replacement is desired, investigate whether the selected implementation supports the exact design and how repeated controls affect weights and variance estimation.
Feasibility is not the same as quality. An optimisation solver can return a mathematically valid set of pairs even when some distances are substantively unacceptable. Inspect pair distances and not only the total objective. A low total could hide one poor pair offset by many excellent pairs.
Numerical tolerance is part of reproducibility
The MatchIt documentation exposes a tolerance passed to the underlying optimisation routine. The matching-methods vignette notes that a lower value can be appropriate for smaller problems. Record the package versions, tolerance, distance specification, restrictions, ratio, and random seeds used elsewhere in the workflow.
Do not imply that many decimal places create substantive certainty. Tolerance concerns the numerical optimisation criterion. It cannot repair poor covariate measurement, lack of overlap, unmeasured confounding, or an inappropriate estimand.
Assess balance after optimal matching
The objective minimises pair distance, not covariate imbalance directly. The official MatchIt balance guide states that balance is not guaranteed in observational matching and must be assessed.
Calculate standardised mean differences before and after matching for every prespecified covariate. Examine variance ratios and empirical distribution differences for important continuous variables. Report proportions for categorical levels. Love plots, density plots, empirical cumulative distribution plots, and pair-distance distributions can reveal problems hidden by a single average.
Do not use null-hypothesis tests as the main balance criterion. Their p-values depend strongly on sample size, which matching deliberately changes. Effect-size measures and distributional plots are more informative.
Optimised distance is not optimised balance
A smaller sum of pair distances does not guarantee smaller standardised differences for every covariate. The distance may weight variables differently from their relevance to the outcome. Two algorithms can have similar objective values but different tail behaviour or subgroup balance.
Compare the primary optimal specification with a defensible greedy nearest-neighbour design while keeping the distance and restrictions constant. If both achieve similar balance and retention, the simpler method may be sufficient. The MatchIt vignette explicitly notes that the two methods often produce similar matched samples.
Assess balance on original covariates, prespecified nonlinear functions, and important interactions. A well-balanced propensity score alone does not show that age, baseline symptoms, site, and previous therapy are balanced.
| Quality domain | Useful diagnostic | Warning sign |
|---|---|---|
| Mean balance | Absolute standardised mean differences | Important covariates remain meaningfully different |
| Spread | Variance ratios and density plots | Similar means but different dispersion |
| Tails | Quantiles and empirical cumulative distributions | Extreme participants remain incomparable |
| Pair quality | Distribution and maximum of pair distances | One or more forced distant pairs |
| Retention | Participant flow by group | Large or selective loss changes the target |
| Subgroups | Balance by site or prespecified subgroup | Overall balance hides local imbalance |
Analyse outcomes in the matched design
Finish the design before viewing exposure-effect estimates. Stuart’s peer-reviewed review of matching methods separates the design stage, which uses background covariates, from outcome analysis. This separation reduces the risk of constructing a sample that favours a desired result.
Paired observations are not an ordinary independent sample. Use an outcome model and uncertainty estimator that reflect matched subclasses, weights, clustering, repeated measures, and the target estimand. The exact approach depends on whether the outcome is continuous, binary, ordinal, count, or time to event.
Regression adjustment in the matched sample can improve precision and address small residual imbalances, but it does not excuse a failed design. Specify the effect scale before analysis. For applied psychology, an adjusted mean difference or absolute risk difference is often easier to interpret than a relative measure alone.
Report effect size and uncertainty
Report the effect estimate, confidence interval, and an interpretation on the outcome’s meaningful scale. Avoid treating statistical significance as the only conclusion. Consider whether the interval includes effects that would matter clinically, educationally, or practically.
Explain how standard errors accounted for pair membership. If the data include school, clinic, therapist, or repeated-participant clustering, account for that structure as well. Matching does not remove dependence that already exists in the sampling or treatment process.
Do not claim that optimal matching has controlled all confounding. It improves measured baseline comparability under the chosen design. Unmeasured motivation, clinician judgement, access barriers, measurement error, and poorly recorded severity can remain.
Compare optimal pair matching with related methods
Greedy nearest-neighbour matching is faster and selects pairs sequentially. Optimal pair matching considers the collective assignment, avoiding matching-order decisions. Neither directly optimises balance, and their matched samples can be nearly identical.
Optimal full matching forms variable-size subclasses, potentially retaining all eligible units and targeting different estimands. It uses weights based on subclass membership and may have a reduced effective sample size even when nominal retention is high.
Cardinality matching selects the largest subset that satisfies prespecified balance constraints. Its objective concerns sample size under balance requirements, not total pair distance. Genetic matching searches for distance weights intended to improve balance, then applies a matching procedure. These are related optimisation ideas but not interchangeable techniques.
Choose the method through the estimand, overlap, balance, retention, interpretability, and computational demands. Avoid selecting a method because the label sounds more sophisticated.
Sensitivity analyses and robustness checks
Prespecify a limited set of defensible alternatives. Compare optimal and greedy pairing using the same distance, a tighter caliper, one-to-one and variable-ratio designs, propensity-score and Mahalanobis distances, or alternative exact restrictions. Summarise how balance, retention, pair distances, and estimates change.
Analyse sensitivity to unmeasured confounding using a method appropriate to the matched effect estimate. Such analysis does not identify missing confounders. It asks how strong an unmeasured bias would need to be to change the conclusion.
Missing data require their own plan. Complete-case analysis can change the eligible population. If multiple imputation is justified, repeat the matching and outcome analysis within each imputed dataset and pool results with methods appropriate to the full procedure. Do not match once on a single convenient imputation and ignore design uncertainty.
Maintain a design log
Record each specification, the reason it was considered, the balance results, and whether outcomes remained hidden. Archive code, software versions, seeds, distance matrices when feasible, and participant-flow counts. A transparent log distinguishes principled design improvement from outcome-driven searching.
Common mistakes and practical repairs
Calling the result globally optimal: state the exact objective, distance, constraints, and tolerance. Optimality is conditional on those choices.
Skipping overlap checks: inspect exposure-group distributions and prohibit implausible matches before optimisation.
Matching on post-treatment variables: rebuild the causal timeline and restrict design variables to genuine baseline measures.
Reporting only the total distance: show balance, pair-distance distribution, worst pairs, retention, and subgroup diagnostics.
Assuming optimal means better than greedy: compare their diagnostics under the same distance and restrictions.
Ignoring paired dependence: use weights and variance estimation that respect matched subclasses and existing clusters.
A reproducible workflow
- Define eligibility, exposure strategies, time zero, follow-up, outcome, and estimand.
- Select pre-exposure covariates using substantive knowledge and a causal model.
- Audit missingness, measurement quality, collinearity, outliers, and overlap.
- Choose and document the distance, exact restrictions, calipers, ratio, and tolerance.
- Run optimal matching without consulting outcome effects.
- Inspect convergence, participant retention, total distance, and worst-pair distances.
- Assess covariate balance on original variables, nonlinear terms, and key subgroups.
- Revise only for documented design reasons, then freeze the specification.
- Fit an outcome model that respects matching weights, subclasses, and clustering.
- Run prespecified sensitivity checks and report remaining assumptions.
Frequently asked questions
Does optimal pair matching guarantee the best balance?
No. It minimises the selected total pair-distance criterion. Covariate balance is a separate property and must be checked for all prespecified variables.
How is it different from nearest-neighbour matching?
Nearest-neighbour matching usually forms pairs sequentially, so matching order can matter without replacement. Optimal pairing solves the collective assignment problem and does not require a focal-unit order.
Can it use Mahalanobis distance?
Yes. Optimal pairing can minimise Mahalanobis distances, propensity-score distances, or another supported distance. The distance determines what closeness means, while the algorithm determines the collective assignment.
Should every exposed participant be matched?
Only when acceptable controls exist. Calipers and support restrictions may leave some participants unmatched. Forced distant matches can increase bias, and exclusions must be reported because they change the represented population.
Is optimal pair matching suitable for large datasets?
It may become computationally demanding because the optimisation can require a full distance matrix. Greedy or faster full-matching methods may be more practical, subject to balance and estimand requirements.
What does the tolerance setting mean?
It controls how precisely the numerical optimiser determines that the distance objective has been solved. It does not measure causal validity, covariate quality, or residual confounding.
What should the dissertation report?
Report the estimand, timeline, covariates, distance, restrictions, caliper, ratio, tolerance, software versions, exclusions, pair-distance summaries, balance diagnostics, outcome model, variance method, and sensitivity analyses.
Conclusion
Psychology dissertation optimal pair matching is valuable when collective pair assignment can avoid order-sensitive greedy choices. Its credibility depends on the causal question, baseline covariates, distance, overlap restrictions, balance, and analysis, not on the optimisation label.
If you need support, use ethical methodological guidance that helps you justify and reproduce each design decision while leaving data ownership, interpretation, and authorship with you. A sound review should test assumptions and strengthen your independent understanding rather than promise a favourable result.