
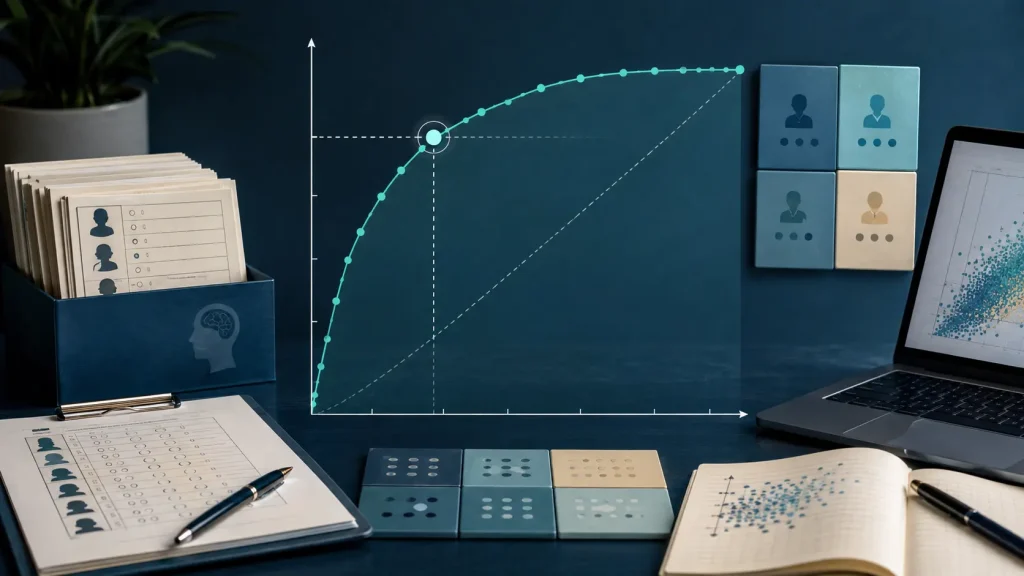
Psychology dissertation ROC curve analysis evaluates how well a continuous score or prediction separates two defined outcome groups across possible thresholds. It can quantify discrimination, show sensitivity-specificity trade-offs, and support threshold evaluation for a screening measure. It cannot establish diagnosis, causality, calibration, or usefulness on its own.
This guide explains the target condition, reference standard, participant spectrum, receiver operating characteristic curve, area under the curve, threshold selection, predictive values, uncertainty, validation, psychology-specific examples, and transparent reporting. The aim is a defensible analysis that matches the intended use of the score.
What psychology dissertation ROC curve analysis answers
A receiver operating characteristic curve describes the performance of a score over all observed decision thresholds for a binary target. At each threshold, the vertical axis shows sensitivity, also called the true-positive rate. The horizontal axis shows one minus specificity, also called the false-positive rate.
The Columbia University ROC guide explains this threshold-by-threshold relationship and distinguishes sensitivity, specificity, positive predictive value, and negative predictive value. A curve is therefore a summary of discrimination across thresholds, not a single classification rule.
In psychology, an index score might be a brief anxiety screener, cognitive-task measure, observer rating, or predicted probability from a model. The binary target might be a structured-interview classification, a clearly defined behavioural outcome, or another defensible reference criterion. Name both variables, the direction of higher scores, the population, and the intended use before analysing the curve.
| Question | Suitable ROC output | What it cannot decide alone |
|---|---|---|
| Does the score rank positive cases above negative cases? | AUC with confidence interval | Whether predictions are well calibrated |
| What happens across possible cut-offs? | ROC curve and threshold table | Which error trade-off is ethically best |
| How does one threshold perform? | Sensitivity, specificity, and confusion matrix | Performance in a population with different prevalence |
| Do two scores differ in discrimination? | Paired or independent AUC comparison | Whether the difference is practically useful |
| Is a model ready for use? | ROC plus validation evidence | Fairness, net benefit, feasibility, or implementation safety |
Define the target condition and reference standard
ROC analysis requires a meaningful binary reference classification. In a dissertation evaluating a brief depression screener, the target might be current probable depressive disorder according to a structured interview administered by trained assessors. A convenient split of the screener itself cannot serve as an independent reference standard for evaluating that same screener.
The STARD 2015 checklist defines the index test as the test being evaluated and the reference standard as the best available method for establishing the target condition. It also asks researchers to explain indeterminate results, missing data, sample-size determination, participant flow, accuracy estimates, precision, bias, and generalisability.
Protect the reference standard from review bias
Where feasible, the assessor applying the reference standard should not know the index score or chosen threshold. If the reference judgement incorporates the index score, agreement may be inflated. Report who administered each assessment, training, masking, order, and the interval between assessments.
Recruit the population in which the score will be used
A sample containing only very clear cases and unusually healthy controls can make discrimination appear stronger than it will be in routine student, community, workplace, or clinical populations. Include the relevant range of severity, comorbidity, language background, age, and alternative explanations for symptoms.
Case-control sampling can estimate sensitivity, specificity, and AUC under stated conditions, but it usually does not reproduce population prevalence. Consequently, predictive values calculated from the sampled case proportion may not describe real-world use. Explain recruitment and intended generalisation precisely.
Understand the classification quantities
At one chosen threshold, each participant falls into one of four cells. A true positive meets the reference condition and screens positive. A false negative meets the condition but screens negative. A true negative does not meet the condition and screens negative. A false positive does not meet the condition but screens positive.
- Sensitivity is the proportion of reference-positive participants classified positive.
- Specificity is the proportion of reference-negative participants classified negative.
- Positive predictive value is the proportion of positive classifications that are reference positive.
- Negative predictive value is the proportion of negative classifications that are reference negative.
- Positive and negative likelihood ratios describe how test results change odds under defined conditions.
Sensitivity and specificity are properties estimated for a threshold in a sampled population and measurement process. Predictive values additionally depend strongly on prevalence. Report confidence intervals because a percentage calculated from a small number of positive or negative cases can be imprecise.
Build and interpret the ROC curve
Software orders the observed scores and evaluates possible thresholds. Lowering a threshold often detects more reference-positive participants, increasing sensitivity, but also labels more reference-negative participants as positive, reducing specificity. The curve displays this trade-off.
Interpret the area under the curve
The area under the curve, or AUC, can be interpreted as the probability that a randomly selected reference-positive participant receives a higher score than a randomly selected reference-negative participant, subject to the direction and tie handling used. An AUC near .50 indicates chance-level ranking, while 1.00 indicates perfect sample separation.
Do not rely on generic labels such as acceptable, good, or excellent without context. An AUC of .75 may be useful for low-cost preliminary screening but inadequate for a high-consequence decision. The confidence interval, target population, reference standard, available alternatives, and error consequences matter more than a label.
Use partial AUC only for a prespecified operating region
A full AUC weights performance across the complete specificity range. If the practical task requires very high sensitivity or very high specificity, performance elsewhere may be irrelevant. A partial AUC can focus on the prespecified region, but the range, standardisation, and rationale must be stated before inspecting results.
The peer-reviewed pROC methods paper describes full and partial AUCs, confidence intervals, smoothing, and statistical comparison of paired or independent ROC curves. It notes that a partial region can be defined by sensitivity or specificity.
Select a threshold responsibly
The threshold is a decision rule, not a purely statistical discovery. Its choice should reflect the intended role of the score and the relative consequences of false negatives and false positives. For a first-stage screener followed by a comprehensive assessment, missing a person who needs evaluation may be weighted differently from referring someone who does not ultimately meet the condition.
Avoid treating the Youden index as a universal optimum
The Youden index maximises sensitivity plus specificity minus one. It gives equal mathematical weight to the two error types and does not incorporate prevalence, resource constraints, treatment benefit, stigma, anxiety, or the harms of missed and unnecessary referrals. It can be reported as one descriptive candidate, not automatically the best policy.
Prespecify clinically or psychologically meaningful criteria
Where possible, state a minimum acceptable sensitivity, specificity, or error cost before analysis. If several thresholds remain plausible, report their full trade-offs rather than selecting the one that makes the measure look strongest. Thresholds derived in the development sample need independent or properly separated validation.
| Threshold strategy | Potential use | Main limitation |
|---|---|---|
| Prespecified published cut-off | Direct validation in a new population | May not transport across languages or settings |
| Minimum sensitivity requirement | Triage where missed cases are costly | Can create many false positives |
| Minimum specificity requirement | Decisions where false positives are costly | Can miss relevant cases |
| Youden index | Descriptive balanced candidate | Ignores prevalence and unequal consequences |
| Cost or utility analysis | Decision-focused threshold | Requires defensible consequence estimates |
Distinguish discrimination from calibration
ROC analysis assesses ranking discrimination. A prediction model can rank participants correctly while producing probabilities that are systematically too high or too low. Calibration asks whether predicted risks agree with observed outcome frequencies. The two properties are different.
If a dissertation develops a multivariable prediction model, report both discrimination and calibration. The TRIPOD+AI reporting guidance applies to studies developing or evaluating prediction-model performance. ROC evidence alone does not satisfy a complete prediction-model evaluation.
For binary regression, explain the model before presenting its ROC curve. The psychology dissertation logistic-regression guide covers coding, functional form, separation, influence, adjusted effects, predicted probabilities, and calibration.
Prevent leakage and optimistic accuracy
Using the same data to select items, transform predictors, fit a model, choose a threshold, and report final performance produces optimism. Every data-dependent step can overfit. Splitting a small data set once is not always efficient, but evaluating the development process on the data that created it is not honest validation.
Internal validation can use bootstrapping or cross-validation when the full modelling and threshold-selection procedure is repeated within each resample or fold. Validation estimates should reflect preprocessing, feature selection, and tuning. The bootstrap confidence-interval guide explains why the resampling unit must preserve the design.
External validation uses genuinely separate participants from the target setting and is stronger evidence of transportability. If only apparent performance is available, call it apparent performance and avoid claims of readiness for practice.
Plan sample size and uncertainty
ROC precision depends on the numbers of reference-positive and reference-negative participants, the anticipated AUC or operating-point accuracy, the confidence level, and the analysis aim. Total sample size alone is uninformative when one outcome group is rare.
Plan around the main estimand. A study estimating sensitivity at a fixed threshold needs enough reference-positive participants. Specificity requires enough reference-negative participants. An AUC comparison requires assumptions about both curves, pairing, correlation, and the smallest relevant difference.
Report confidence intervals for AUC, sensitivity, specificity, predictive values, and important threshold estimates. If the curve shows perfect separation in a small sample, do not report false certainty. The current official pROC documentation explicitly warns that some methods return a misleading zero-width interval when sample AUC equals 1.
Compare ROC curves with the correct dependence
Two scores measured on the same participants produce paired ROC curves. Their AUC estimates are correlated, so a method for independent curves is inappropriate. Software can apply a paired nonparametric comparison such as the DeLong approach or a supported paired bootstrap.
When curves come from separate samples, an independent comparison may be required. Report whether curves were paired, the comparison method, the AUC difference with confidence interval, and the population represented by each sample. Statistical difference does not establish that one score offers better decisions or is worth additional cost.
Comparing a newly fitted model with a baseline model on the same development data is especially optimistic. Use a validation procedure that preserves pairing and includes the entire modelling pipeline. If the task is multiclass rather than binary, justify the multiclass metric and averaging method instead of applying a binary curve repeatedly without multiplicity control.
Worked psychology screening example
Imagine a dissertation evaluating a six-item distress screener among 420 university students. A structured interview conducted within seven days serves as the reference standard. Interviewers are masked to screener scores. Sixty-eight participants meet the target classification, so the observed prevalence is 16.2%.
The prespecified primary aim is discrimination, with a secondary aim of examining thresholds suitable for a low-cost first-stage referral. The AUC is .82 with a 95% confidence interval of [.77, .87]. This indicates useful sample discrimination but leaves uncertainty and does not prove diagnostic sufficiency.
At the published threshold of 9, sensitivity is .84 and specificity is .70. At threshold 11, sensitivity falls to .72 while specificity rises to .82. The lower threshold may suit an initial screen if missed cases are considered more harmful and follow-up assessment is available. The study reports both operating points rather than claiming one is objectively optimal.
The dissertation also reports the confusion matrices and predictive values with confidence intervals. It notes that predictive values may change in settings with different prevalence. A bootstrap internal-validation analysis repeats score construction and threshold evaluation, showing modest optimism. No claim is made that the threshold should be adopted without external validation.
| Result | Illustrative estimate | Responsible interpretation |
|---|---|---|
| Reference-positive participants | 68 of 420 | Precision depends strongly on this count |
| AUC | .82, 95% CI [.77, .87] | Ranks groups reasonably well in this sample |
| Threshold 9 | Sensitivity .84; specificity .70 | Fewer missed cases, more false positives |
| Threshold 11 | Sensitivity .72; specificity .82 | More missed cases, fewer false positives |
| Validation | Bootstrap optimism assessment | Internal evidence, not external transportability |
Software workflow
Before running software, verify reference coding, score direction, missingness, duplicate participants, and the timing of assessments. Plot score distributions by reference group. Specify whether higher or lower scores indicate the target condition.
In R, pROC can build curves, calculate total or partial AUCs, obtain confidence intervals, extract threshold coordinates, and compare curves. Record the R version, package version, function arguments, direction, confidence method, bootstrap settings if used, and whether curves were paired.
SPSS, Stata, SAS, jamovi, and other packages can produce ROC output, but defaults differ. Check how ties, direction, missing data, confidence intervals, and threshold coordinates are handled. Exporting a polished curve does not replace validation or a written analysis plan.
Report the study transparently
The EQUATOR Network STARD record states that the guideline aims to improve complete and transparent reporting so readers can assess bias and generalisability. Psychology studies evaluating screening accuracy should adapt relevant STARD items even when the target is not a medical diagnosis.
- Define the population, setting, recruitment dates, inclusion criteria, and sampling method.
- Describe the index score, reference standard, masking, assessors, timing, and indeterminate results.
- State whether thresholds were prespecified, published, or selected from the data.
- Report participant flow, missing data, exclusions, and the numbers in each reference group.
- Provide AUC and confidence interval, the plotted curve, and important operating points.
- Report confusion matrices, sensitivity, specificity, predictive values, and precision where relevant.
- Describe development, internal validation, external validation, and optimism correction separately.
- Discuss prevalence, spectrum effects, fairness, error consequences, and transportability.
Common ROC analysis mistakes
- Creating the reference classification by splitting the same score being evaluated.
- Calling an AUC a measure of calibration or overall usefulness.
- Choosing a threshold solely because it maximises the Youden index.
- Reporting sensitivity without specificity, or vice versa.
- Ignoring prevalence when interpreting positive and negative predictive values.
- Using clear cases and extreme controls, then generalising to routine populations.
- Selecting features and testing performance on the same participants without correction.
- Comparing paired curves with an independent-sample method.
- Reporting AUC without a confidence interval or participant-group counts.
- Claiming that good discrimination proves causality, fairness, safety, or readiness for practice.
Frequently asked questions
What does AUC mean in a psychology dissertation?
It summarises how well a score ranks reference-positive participants above reference-negative participants across thresholds. It does not measure calibration or choose a decision threshold.
Is an AUC of .70 acceptable?
There is no universal boundary. Interpret magnitude and uncertainty in relation to the intended use, consequences, population, reference standard, and alternatives.
How should I choose the best cut-off?
Prespecify the decision goal and error consequences. Report several meaningful operating points and validate any data-derived threshold in separate or properly resampled data.
Why do predictive values change across settings?
Positive and negative predictive values depend on the prevalence of the target condition as well as sensitivity and specificity. A new setting can therefore produce different values.
Can ROC analysis validate a psychological scale?
It supplies criterion-related discrimination evidence when a defensible reference standard exists. Full validation also needs construct definition, reliability, internal structure, response-process evidence, and fairness. See the psychology dissertation scale-development guide.
Should I compare two AUCs?
Compare them only when the difference answers a prespecified question. Use a paired method for scores measured on the same participants and report the AUC difference with uncertainty.
Can I use ROC analysis with more than two outcome classes?
Multiclass extensions exist, but their definitions and averaging differ. State the metric, class weighting, validation design, and why it answers the research question.
Conclusion
Psychology dissertation ROC curve analysis is strongest when the target condition, reference standard, population, score direction, threshold purpose, and validation strategy are fixed before results are examined. Report discrimination with uncertainty, show operating-point trade-offs, separate AUC from calibration, and avoid presenting a sample-derived threshold as universal.
If you need dissertation support, choose ethical tutoring that helps you understand, reproduce, and defend your own work. Retain responsibility for the design, code, reference standard, threshold decisions, validation, and interpretation, protect participant information, and follow institutional rules on permitted assistance.


