Psychology dissertation generalized additive models help researchers estimate nonlinear relationships without forcing every association into a straight line or choosing arbitrary categories. This guide explains when a GAM is justified, how smooth terms work, how to choose the outcome family and basis dimension, which diagnostics matter, and how to report curves without overstating what observational data can show.
What generalized additive models estimate
A generalized additive model, or GAM, extends a generalized linear model by allowing the linear predictor to contain smooth functions of one or more predictors. Instead of assuming that each one-unit increase in age, stress, sleep or exposure has the same effect everywhere, the model estimates a curve whose shape is informed by the data and controlled by a smoothness penalty.
The recent peer-reviewed Annual Review of Statistics overview defines GAMs as models whose linear predictor includes sums of smooth functions with shapes that are estimated. The framework can accommodate Gaussian, binary, count and other outcomes while preserving an explicit regression structure.
Suppose a dissertation examines whether nightly sleep duration predicts next-day executive functioning. A straight-line model says that every additional hour has the same association. A quadratic model permits one bend but fixes a particular mathematical shape. A GAM can estimate a gradual rise, plateau and possible decline while penalising unnecessary wiggles.
Flexibility does not remove the need for theory. The fitted curve is conditional on the selected outcome family, covariates, sampling design, smooth basis, penalty and available predictor range. A complex-looking curve is not automatically a psychological mechanism.
Table of Contents
GAMs compared with familiar regression models
| Approach | Shape assumption | Useful when | Main limitation |
|---|---|---|---|
| Linear regression | Constant slope | A straight-line association is plausible | Misses thresholds, plateaus and reversals |
| Polynomial regression | Preselected polynomial order | A simple curved shape has theoretical support | High orders can behave poorly near boundaries |
| Categories | Step changes at cut points | Categories are substantively defined | Discards information and makes arbitrary discontinuities |
| Generalized additive model | Penalised smooth function | Shape is uncertain but expected to be smooth | Needs adequate data, careful diagnostics and graphical interpretation |
| Generalized additive mixed model | Smooth effects plus dependence structure | Repeated or clustered data have nonlinear trends | Extra complexity can exceed the information available |
A GAM should not be selected merely because it produces a lower p-value. Start with the research question. If the primary hypothesis concerns a constant linear effect, a linear term may answer it more directly. If theory predicts an unknown threshold, saturation, sensitive period or recovery curve, a prespecified smooth can be appropriate.
Why categorising a continuous predictor is usually weak
Splitting age, symptoms or exposure into low, medium and high groups reduces resolution and makes results depend on chosen cut points. A smooth term retains the observed scale and can reveal gradual changes. It also avoids implying that two people just either side of a cut point are meaningfully different while two people far apart within one category are equivalent.
Why a GAM is not fully assumption-free
The analyst still chooses predictors, outcome distribution, link function, additive structure, interactions and dependence model. Smoothness is estimated rather than freely drawn through every observation. The official mgcv GAM documentation explains that penalised regression splines balance fit against wiggliness and estimate the degree of smoothness during model fitting.
Plan a psychology dissertation generalized additive models study
Write the estimand before the formula. State the outcome, population, observation window, predictor contrast and whether interest lies in description, prediction or a causal effect. For example: estimate the adjusted mean difference in anxiety score across the observed range of weekly social-media use, allowing the association to be nonlinear.
Specify which predictors need smooth terms and which remain linear or categorical. Avoid smoothing every continuous variable by default. A nuisance variable can still require a smooth if linear adjustment would leave important residual confounding, but each decision needs a design or subject-matter reason.
Choose the outcome family and link
The outcome determines the distributional starting point. Approximately continuous outcomes may use a Gaussian family with identity link. Binary outcomes commonly use a binomial family with logit link. Event counts may require Poisson or negative binomial models, sometimes with an exposure offset. Ordered or bounded measures may need a more suitable family rather than automatic Gaussian modelling.
Check whether the family reproduces the outcome’s variance, zeros, tails and boundaries. A smooth mean cannot repair an unsuitable distribution. For counts, consult the Poisson regression guide and the negative binomial regression guide before adding nonlinear terms.
Prespecify plausible complexity
List the focal smooths, covariates, interactions, subgroup comparisons and sensitivity analyses before examining many curves. The goal is not to discover the most visually interesting line. Prespecification reduces researcher degrees of freedom and makes the final model easier to defend.
Plan how sparse regions will be handled. A dataset may contain many observations near the mean of a predictor and very few at the extremes. The curve is least certain where information is thin, so predictions and interpretations should stay within the supported range.
Understand splines, penalties and effective degrees of freedom
A smooth term is represented by a set of basis functions. Their weighted combination creates the estimated curve. The basis dimension, often written as k, limits the size of the function space. A penalty discourages excessive curvature, and a smoothing parameter controls how strongly that penalty acts.
These roles are different. Increasing k does not command the model to become wiggly; it raises the maximum complexity available. The penalty can still shrink the fitted curve toward a simpler form. Conversely, a k that is too small can prevent the model from representing a real pattern.
Read effective degrees of freedom carefully
Effective degrees of freedom, or EDF, summarise the fitted complexity of a smooth. An EDF near one usually indicates an approximately linear contribution. Larger values indicate more curvature, but EDF is not the number of turning points and does not by itself measure substantive importance.
Report EDF with the estimated curve, uncertainty band and predictor distribution. A statistically detectable smooth with limited outcome change may have little practical relevance. A curve with a broad uncertainty band can be too imprecise to support detailed claims about thresholds.
Choose and check the basis dimension
The official mgcv basis-dimension guidance states that k should be large enough to represent the underlying pattern but small enough for computational efficiency. It recommends checking residual pattern, EDF relative to the available maximum, and stability after increasing a suspect value.
Do not repeatedly raise k until the preferred result appears. Select a defensible starting value, run the diagnostic, refit a limited sensitivity model with a larger basis, and document whether the scientific conclusion changes.
Specify main effects and nonlinear interactions
Additive smooths estimate separate contributions such as a smooth of age plus a smooth of sleep. This assumes that the shape for one predictor does not change across the other predictor unless an interaction is included. Test an interaction only when it answers a planned question and the sample covers the joint predictor space.
Group-specific smooths
A dissertation might ask whether a developmental trajectory differs by intervention group. Group-specific smooths can estimate a separate curve for each group, but the model also needs appropriate group main effects and an identifiable parameterisation. Compare curves through predicted differences with uncertainty rather than judging whether two separate significance tests cross 0.05.
Tensor-product interactions
When two predictors use different units or scales, tensor-product smooths can estimate a nonlinear surface. For example, the association between sleep and attention may vary across age. Such surfaces need substantial coverage across combinations of sleep and age. Empty corners of the data space create extrapolation that a colourful plot can hide.
Use an interaction decomposition that makes the main smooths and additional interaction identifiable. Report why the interaction was included, its basis choices and how the surface was converted into interpretable contrasts or slices.
Handle repeated measures and clustered psychology data
Daily diaries, intensive longitudinal studies, therapy sessions and school samples violate independence when observations are nested within people, therapists or institutions. A standard GAM does not solve this dependence merely by smoothing time. Consider random effects, participant-specific smooths, autocorrelation structures or another model matched to the design.
Participant-specific smooths can require many coefficients and sufficient observations per participant. A population smooth with random intercepts may be more realistic for a modest dissertation dataset. The multilevel modelling guide explains the distinction between population-average and cluster-specific questions.
Model time as more than a nuisance variable
Time trends can reflect learning, fatigue, seasonality, treatment response or measurement drift. Decide whether time is the focal process, an adjustment variable or both. For cyclic patterns such as day of week or time of day, use a cyclic basis when the endpoints should join.
Residual autocorrelation after modelling the mean can make uncertainty too narrow. Inspect residuals by lag and participant. If dependence remains, use a defensible correlation structure or robust alternative supported by the software and design.
Plan sample size and power
There is no universal observations-per-smooth rule. Information depends on outcome family, effect shape, noise, predictor distribution, number of smooths, basis dimensions, clustering, missingness and the target contrast. A sample concentrated in a narrow range cannot estimate a detailed curve at the extremes regardless of its total size.
Simulation is the most transparent planning strategy. Generate predictor distributions and outcomes under plausible linear, curved and null relationships. Reproduce clustering and missingness. Fit the planned model and assess convergence, interval coverage, false positives, power for meaningful contrasts and curve recovery. The power analysis guide provides a framework for design-specific simulation.
| Planning element | Questions to simulate | Warning sign |
|---|---|---|
| Predictor coverage | Are all important ranges represented? | Very few observations support a claimed threshold |
| Curve shape | Can linear, plateau and reversal scenarios be recovered? | Estimated wiggles change across small samples |
| Outcome family | Are variance, zeros and boundaries realistic? | Bias or poor interval coverage |
| Dependence | Are participant and site correlations reproduced? | False-positive rates exceed the target |
| Missingness | How do plausible mechanisms affect the curve? | Complete-case and sensitivity results diverge |
Fit the model transparently
Record the software, package and version; outcome family and link; formula; smooth basis; basis dimensions; smoothing-selection method; penalties; random effects; correlation structure; weights; offsets; and missing-data handling. Keep code and an analysis log so the reported model can be reproduced.
Restricted maximum likelihood is commonly used for smoothing-parameter estimation, but the choice should follow the software’s documented behaviour and the comparison being made. Do not compare models with different fixed-effect structures using criteria that are not valid for that purpose.
Check convergence and identifiability
Review optimiser warnings, gradients, smoothing parameters, fitted values and numerical rank. A printed result table is not proof of convergence. Sparse binary outcomes, excessive terms or weakly identified smooth interactions can produce unstable estimates.
Concurvity is the smooth-model analogue of problematic collinearity: one smooth contribution may be approximated by other terms. High concurvity can make individual curves unstable even when overall predictions look adequate. Investigate overlapping variables, redundant time trends and overly complex interactions rather than deleting terms solely to improve a number.
Run diagnostics that address the whole model
Use residual plots appropriate to the outcome family. Check residuals against fitted values, each predictor, time, clusters and omitted design variables. Examine whether the model reproduces the response distribution, not only the conditional mean. For non-Gaussian outcomes, simulation-based diagnostics can be clearer than ordinary residuals.
The official mgcv model-checking documentation covers convergence information, residual plots and simulation-based checks of whether basis dimensions may be too low. Treat its p-values as diagnostic signals, not automatic pass-or-fail decisions.
Inspect influence and boundary behaviour
A few observations can shape a curve, especially near predictor boundaries. Verify data entry and measurement, inspect leverage or case-deletion stability, and compare fits with prespecified robust or influence analyses. Do not remove valid extreme observations simply because the curve becomes smoother. See the outlier analysis guide.
Use out-of-sample checks when prediction matters
Random cross-validation can leak information when repeated observations from one participant appear in both training and test sets. Split at the participant, site or time level that represents future use. Evaluate calibration and prediction error across meaningful subgroups and predictor ranges.
Interpret curves without inventing thresholds
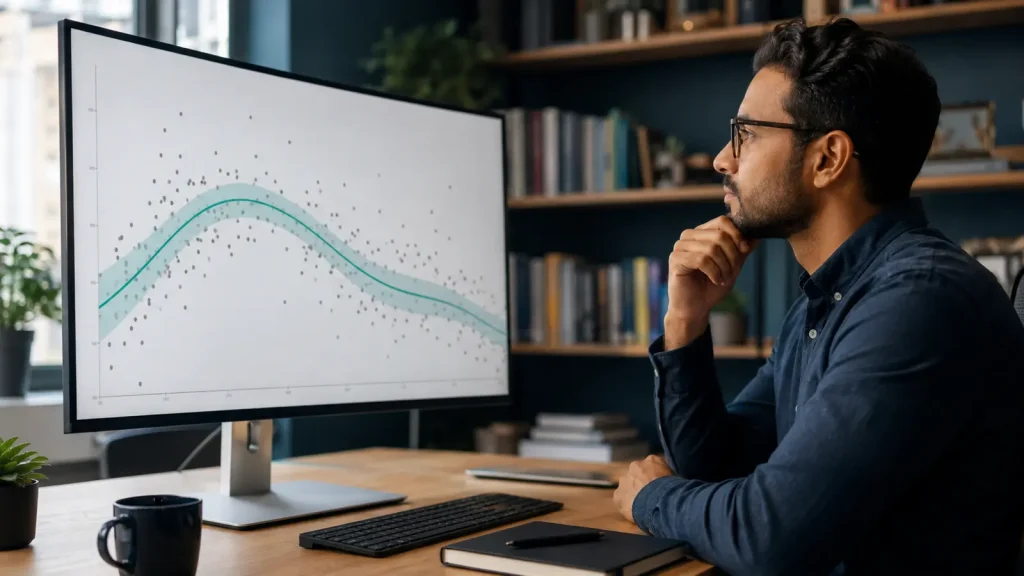
Plot predicted outcomes or link-scale effects over an observed predictor grid with uncertainty bands and a rug, histogram or density showing data support. State which covariates are held constant or averaged over. Response-scale predictions are often easier to explain than centred smooth contributions.
A point where a curve appears to bend is not automatically a statistically established threshold. Estimate planned contrasts, derivatives or regions where the slope differs credibly from zero when those quantities match the question. Account for simultaneous uncertainty when making claims across an entire curve rather than at one selected point.
Psychology-specific interpretation example
Imagine a study of perceived stress across weekly caregiving hours. The fitted curve is nearly flat from zero to ten hours, rises from ten to thirty hours, then levels off. A responsible result describes adjusted predicted stress across supported caregiving values and gives uncertainty for meaningful contrasts.
It would be inappropriate to claim that ten hours causes a stress threshold unless the design supports causality and the threshold was formally estimated. Confounding, reverse direction, measurement error and sparse data at high hours remain possible explanations. Consult the confounding variables guide before using causal language.
Handle missing data and measurement quality
Missing outcomes and predictors can change both the estimated curve and its supported range. The mgcv missing-data documentation notes that ordinary defaults generally use complete cases, which can waste information when covariate missingness is extensive.
Describe missingness by variable and predictor range. If using multiple imputation, make the imputation model compatible with nonlinearity, interactions, clustering and the outcome. Combine predictions or contrasts using a method appropriate to multiply imputed data rather than fitting one convenient completed dataset. The missing data guide provides broader planning principles.
Report generalized additive models clearly
| Report section | Minimum information |
|---|---|
| Research question | Outcome, population, predictor range, estimand and purpose |
| Design | Sampling, clustering, time structure, exclusions and missingness |
| Model | Family, link, parametric terms, smooths, interactions and offsets |
| Smoothing | Basis type, k, penalty and selection method |
| Diagnostics | Residuals, basis check, concurvity, influence and dependence |
| Results | EDF, uncertainty, predicted curves and planned contrasts |
| Sensitivity | Linear alternative, larger basis, family and missing-data checks |
| Limitations | Sparse ranges, observational limits and exploratory choices |
Include plots that remain readable in grayscale and on small screens. Label axes with real units, show observed data support, define the reference values and avoid reporting only a global p-value for a smooth. Archive code, seeds and package versions where ethics and data agreements permit.
Common mistakes to avoid
- Smoothing every continuous variable without a research reason.
- Choosing a GAM after a linear result is not statistically significant.
- Using an unsuitable outcome family and expecting a smooth to fix it.
- Setting a restrictive basis dimension and skipping the basis check.
- Interpreting EDF as the number or importance of psychological stages.
- Claiming a threshold from a visual bend without formal uncertainty.
- Ignoring repeated measures, residual autocorrelation or site clustering.
- Presenting predictions in ranges with almost no observations.
- Hiding model alternatives or sensitivity analyses that change the conclusion.
Frequently asked questions
When should I use a GAM in a psychology dissertation?
Use one when theory permits a smooth but uncertain nonlinear association, the predictor has adequate coverage, and the added flexibility answers the research question more faithfully than a straight line or arbitrary categories.
Is a GAM a nonparametric model?
It is often called semiparametric. Smooth components are flexibly estimated, while the model still has a specified outcome family, link, additive structure and any conventional parametric terms.
What does EDF mean?
Effective degrees of freedom summarise fitted smooth complexity. Values near one suggest an approximately linear contribution; larger values indicate more curvature. Interpret EDF alongside the plotted effect and uncertainty.
How do I choose k?
Choose a basis dimension large enough for plausible complexity, then check it using diagnostics and a limited higher-k sensitivity fit. The smoothing penalty, not k alone, controls the final wiggliness.
Can GAM results establish a psychological threshold?
Not from a visual curve alone. A threshold requires a clear definition, adequate data near the candidate value, formal uncertainty and a design that supports the intended causal or descriptive claim.
Can I use GAMs with repeated measures?
Yes, but the dependence must be modelled. Depending on the design, this may require random effects, participant-specific smooths, autocorrelation structures or a generalized additive mixed model.
How should I present a nonlinear effect?
Show response-scale predictions or clearly labelled partial effects with uncertainty and data density. Add planned contrasts or derivative summaries when they directly answer the research question.
Conclusion
Psychology dissertation generalized additive models are valuable when an association is expected to be smooth but its shape cannot be responsibly fixed in advance. A defensible analysis begins with an estimand, chooses the correct family and dependence structure, controls complexity through penalties, checks basis adequacy and residual behaviour, and interprets predictions only where the data provide support.
If you need statistical tutoring, choose assistance that teaches you to plan, run and explain your own analysis. Protect participant information, follow research ethics and academic-integrity rules, and remain responsible for every modelling decision and statement in the dissertation.