
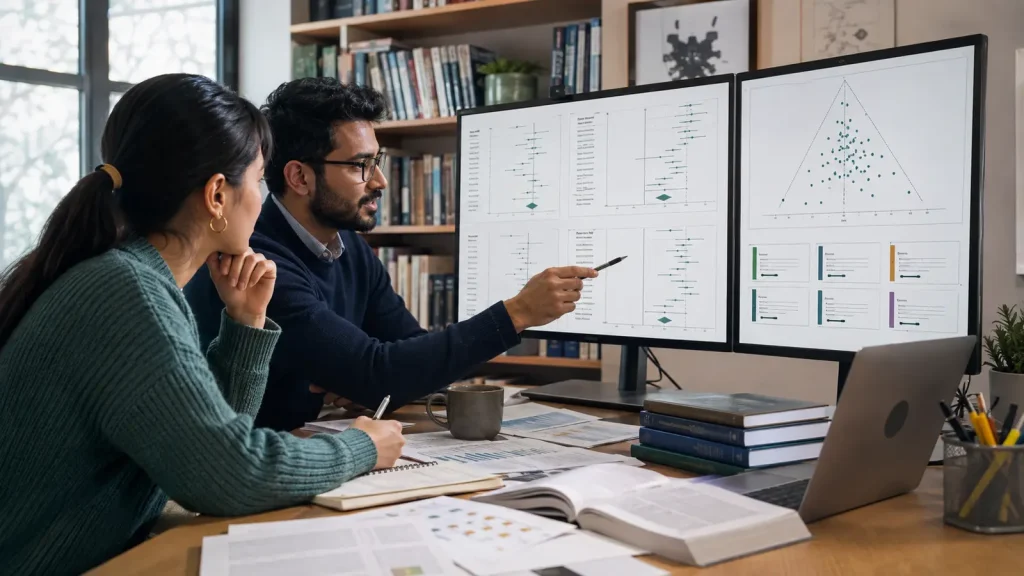
A psychology dissertation meta-analysis combines compatible quantitative findings to answer a focused question with more precision and context than one study alone. It is not an automatic final step after a literature search. A credible synthesis requires a prespecified question, reproducible study selection, comparable effect estimates, correct handling of dependent results, appropriate uncertainty, and conclusions that reflect heterogeneity and bias.
This guide explains the decisions that turn a systematic review into a defensible meta-analysis. It covers eligibility, protocols, effect-size extraction, fixed-effect and random-effects models, heterogeneity, multiple effects from the same study, moderator analysis, publication bias, sensitivity checks, forest plots, reporting, and psychology-specific examples. The emphasis is on transparent reasoning rather than pressing a software button.
What is meta-analysis in a psychology dissertation?
Meta-analysis is a statistical synthesis of effect estimates from two or more studies addressing a sufficiently similar question. Each study contributes an estimate, such as a standardised mean difference, correlation, odds ratio, or risk ratio, together with information about its precision. A model then produces a weighted summary while retaining the contribution and uncertainty of individual studies.
A systematic review and a meta-analysis are related but not identical. The review defines the question, searches for evidence, selects studies, extracts data, and appraises bias. Meta-analysis is one possible synthesis method within that review. If studies are too different in population, construct, design, outcome, or timing, a structured narrative synthesis may be more valid than a pooled number.
The existing systematic review psychology dissertation guide explains the wider review workflow. This article focuses on the additional statistical decisions required when effect estimates will be combined.
| Review component | Purpose | Typical output |
|---|---|---|
| Question and eligibility | Define which evidence can answer the question | Protocol and inclusion criteria |
| Systematic search | Identify eligible evidence reproducibly | Search strategies and PRISMA flow diagram |
| Risk-of-bias appraisal | Assess whether study results may be distorted | Domain-level judgements with reasons |
| Effect-size calculation | Put compatible outcomes on an analysable scale | Effect estimates and sampling variances |
| Meta-analysis | Estimate a summary and between-study variation | Pooled effect, confidence interval, heterogeneity |
| Interpretation | Explain scope, uncertainty, bias, and applicability | Proportionate conclusions |
Decide whether a meta-analysis is appropriate
Pooling is justified by conceptual comparability, not by the availability of numbers. Before calculating anything, examine whether the studies estimate effects that belong in the same synthesis. Consider the population, psychological construct, intervention or exposure, comparator, study design, measurement instrument, follow-up period, and estimand.
For example, trials of cognitive behavioural interventions for university test anxiety might be compatible if they use validated anxiety measures and comparable post-intervention timings. Combining those trials with cross-sectional correlations between perfectionism and anxiety would answer a different question. Converting both into a common numeric scale would not make their causal interpretations equivalent.
Define the review question and estimand
State exactly what quantity the synthesis should estimate. For an intervention review, this might be the average post-treatment difference between intervention and comparator groups. For correlational research, it might be the mean association between social support and depressive symptoms. For prevalence research, it might be the proportion of a defined population meeting a criterion within a specified period.
Define the eligible study designs before searching. Mixing randomised, quasi-experimental, and cross-sectional estimates in one summary can obscure major differences in bias and interpretation. Separate syntheses or design-based subgroup analyses are usually clearer. Use the research-question guide to align the population, variables, comparison, and timeframe.
Write and register a protocol
The protocol should specify the question, eligibility criteria, information sources, search strategy, screening, extraction, risk-of-bias tool, outcomes, effect measures, dependence strategy, synthesis model, heterogeneity assessment, moderators, sensitivity analyses, and reporting plan. Date-stamping or registering it before screening reduces opportunities to make decisions after seeing preferred results. The preregistration guide explains how to separate planned decisions from later exploration.
PRISMA-P provides reporting guidance for systematic review protocols. A dissertation may also use an institutional repository or suitable public registry, subject to supervisor and discipline requirements. Deviations are sometimes necessary, but they should be dated, explained, and labelled rather than silently rewritten.
Table of Contents
Search, screen, and extract reproducibly
A meta-analysis inherits every strength and weakness of its evidence search. Search several relevant bibliographic databases, document the complete strategies, record the final search date, and search sources beyond journal databases when appropriate. Grey literature, theses, trial registrations, preprints, and reference lists may reveal results that journal-only searches miss.
Use at least two independent reviewers for screening and critical extraction when feasible. If a dissertation is completed by one student, arrange a second check on a proportion of records and all included studies. Report the process honestly. A second reviewer reduces errors but does not convert a limited search into a comprehensive one.
Build an extraction dictionary
Define each field before extraction. Record citation, sample characteristics, design, setting, recruitment, intervention and comparator, outcome definition, instrument, time point, sample size, descriptive statistics, adjusted or unadjusted estimate, variance information, risk-of-bias details, and funding or conflicts. Retain page numbers, table identifiers, and calculation notes so every value can be traced.
Contact authors when essential statistics are missing and record attempts. Do not reconstruct results from graphs when more reliable numerical data are available. If graph extraction is necessary, describe the method and test its influence in sensitivity analysis.
Choose and calculate compatible effect sizes
The effect measure should match the outcome and research question. Do not select a measure merely because it is familiar. The Cochrane Handbook’s effect-measure guidance explains how outcome type and study design shape this choice.
| Outcome or question | Common effect measure | Key caution |
|---|---|---|
| Same continuous scale | Mean difference | Higher scores must have the same meaning |
| Different scales for one construct | Standardised mean difference, often Hedges’ g | Scale reliability and construct equivalence still matter |
| Binary outcome | Risk ratio, odds ratio, or risk difference | These measures are not interchangeable |
| Association between continuous variables | Fisher-transformed correlation | Adjusted and unadjusted correlations answer different questions |
| Time-to-event outcome | Hazard ratio | Check proportional-hazards interpretation |
| Prevalence | Proportion on a suitable transformed or modelled scale | Case definition and sampling frame drive comparability |
Standardised mean differences
Use a standardised mean difference when studies measure the same construct on different scales. Hedges’ g includes a small-sample correction and is common in psychology. Align the direction first, so positive values consistently indicate the same outcome. Report the rule used to reverse scores.
Standardisation does not eliminate conceptual differences. A one-standard-deviation unit depends partly on variability within each study, which can differ by population or measurement reliability. Interpret the pooled effect in context and, where possible, translate it back to a familiar scale without overstating clinical or practical meaning. The effect-size guide provides further interpretation principles.
Correlations and adjusted estimates
Correlations are commonly transformed with Fisher’s z for synthesis and converted back for presentation. Avoid pooling raw Pearson correlations with partial correlations unless the estimand and adjustment sets are demonstrably compatible. Different covariate adjustments can change what each effect represents.
For intervention and observational studies, decide whether to extract adjusted or unadjusted estimates. Prefer a prespecified hierarchy based on risk of bias and comparability. Do not select whichever estimate produces the largest or most significant result.
Handle multiple outcomes and dependent effects
Psychology studies frequently report several scales, subscales, time points, intervention arms, or samples. Effect sizes from the same participants are statistically dependent. Treating them as independent gives one study disproportionate influence and usually understates uncertainty.
Plan a hierarchy, such as one validated primary outcome at the first eligible post-treatment time. Other defensible options include combining related outcomes within studies, multivariate meta-analysis, three-level models, or robust variance estimation. The choice depends on the question, number of studies, available correlations, and software expertise.
Pustejovsky and Tipton’s robust variance estimation tutorial explains how dependent effect sizes can be retained when their exact dependence structure is unknown. Small-sample corrections and degrees of freedom matter. A sophisticated estimator cannot compensate for very few independent studies, so report the number of studies as well as the number of effects.
Multi-arm trials also create dependence when two intervention arms share one comparator. Combine eligible arms, split the shared group using an accepted method, or use a multivariate approach. Never count the same comparator participants twice as if they were independent. When study effects are clustered within reports, concepts from the multilevel-modelling guide help explain why independence cannot be assumed.
Choose the synthesis model deliberately
Fixed-effect and random-effects models
A fixed-effect model assumes the included studies share one common true effect and differ only through sampling error. Its inference is conditional on those studies. A random-effects model allows true effects to vary across studies and estimates a mean of a distribution of effects. It is not automatically the correct choice whenever a heterogeneity test is significant.
Psychology studies often differ in participants, settings, implementation, instruments, and follow-up, making genuine variation plausible. A random-effects model may therefore be suitable, but it gives relatively more weight to smaller studies and introduces uncertainty in the between-study variance. The choice and estimator should be prespecified and justified.
The Cochrane Handbook’s meta-analysis chapter stresses that heterogeneity must be considered and random-effects results interpreted carefully. When there are few studies, conventional normal-approximation intervals can be overconfident. Consider methods such as Hartung-Knapp adjustments when appropriate and explain the software settings used.
Weighting and uncertainty
Inverse-variance methods give more weight to estimates with smaller sampling variance. In random-effects analysis, the between-study variance is added to each study’s sampling variance. The weights therefore depend on both within-study precision and estimated heterogeneity.
Report the pooled estimate with a confidence interval. A confidence interval describes uncertainty around the mean effect, not the spread of true effects across settings. When a random-effects model is meaningful and enough studies are available, add a prediction interval to show where a future comparable study’s true effect might plausibly lie.
Measure and interpret heterogeneity
Heterogeneity is variation among study effects beyond sampling error. Examine it conceptually before analysing it statistically. Differences in age, diagnosis, culture, recruitment, intervention intensity, measurement, follow-up, design, and risk of bias may all matter.
Cochran’s Q tests whether observed variation is compatible with sampling error, but it has limited power with few studies and excessive power with many. I-squared describes the proportion of observed variability attributed to heterogeneity rather than sampling error; it does not show the absolute size or clinical importance of variation. Tau-squared estimates the between-study variance on the effect-size scale.
A prediction interval often communicates heterogeneity more directly than I-squared because it describes a plausible range of true effects in comparable settings. Borenstein explains the distinction between I-squared and prediction intervals. Interpret all heterogeneity statistics with the number and precision of studies, not through rigid cutoffs.
Investigate moderators without data dredging
Subgroup analysis and meta-regression can test whether effect sizes vary with study characteristics, such as participant age, intervention duration, delivery mode, measurement instrument, or risk of bias. Define a small number of theory-led moderators in the protocol. Each needs variation across studies and enough independent studies to support estimation.
Do not conclude that a moderator exists because one subgroup is significant and another is not. Test the difference directly. Study-level moderator relationships are observational and can be confounded. They do not necessarily describe individual-level relationships, a problem known as ecological bias.
Avoid stepwise searches across many moderators. With few studies, coefficients can be unstable and confidence intervals wide. Present moderator analyses as exploratory when they were not prespecified, and do not turn a fragile pattern into a recommendation.
Assess study bias and missing evidence
Use a risk-of-bias tool matched to the study design and assess the result being synthesised, not merely the paper. Two reviewers should make independent judgements where possible and support each judgement with evidence. Avoid summing domain ratings into an unvalidated quality score.
Incorporate bias into interpretation and sensitivity analysis. Compare the main synthesis with analyses restricted to studies at lower risk when enough evidence exists. Cochrane’s bias guidance recommends presenting risk-of-bias judgements alongside study results and considering how they affect the synthesis.
Publication bias and selective reporting
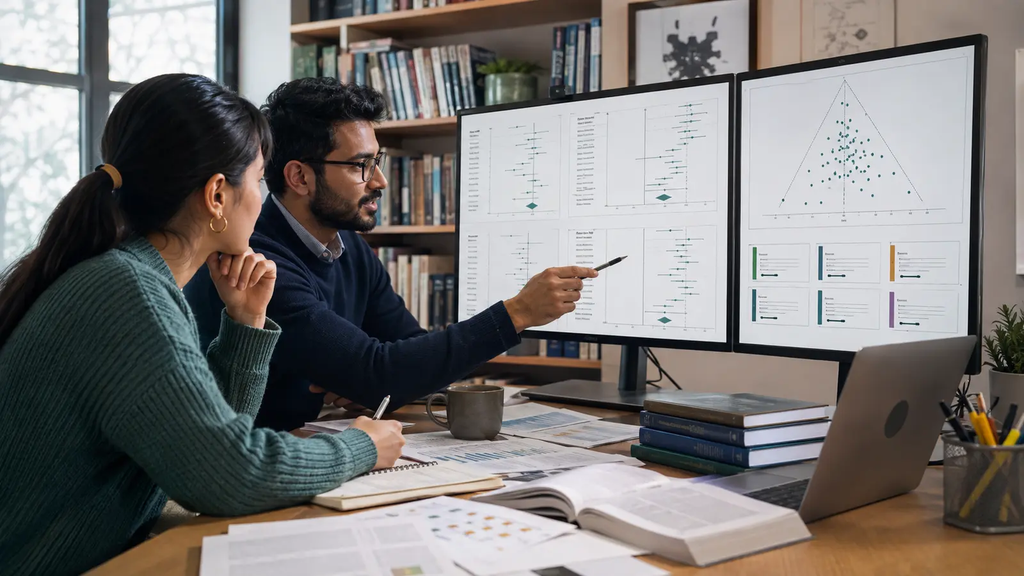
Missing evidence can arise because entire studies are not published or because outcomes and analyses are selectively reported. A funnel plot may reveal asymmetry, but asymmetry can also reflect heterogeneity, small-study design differences, chance, or methodological problems. With few studies, visual and regression-based tests have weak performance.
Compare publications with protocols and registrations, search grey literature, contact investigators, and document unavailable outcomes. Cochrane’s missing-evidence chapter distinguishes missing studies from selective non-reporting within known studies and emphasises assessing consequences for important outcomes. Treat trim-and-fill or significance-based adjustments as sensitivity methods, not automatic corrections that recover truth.
Run a planned sensitivity analysis
Sensitivity checks should address assumptions likely to change the conclusion. Define them before inspecting results where possible.
- Exclude studies at high risk of bias and compare estimates.
- Use alternative justified effect-size or variance calculations.
- Compare reasonable between-study variance estimators and interval methods.
- Change rules for selecting time points or overlapping outcomes.
- Use influence diagnostics and leave-one-study-out analyses.
- Separate study designs, measurement types, or unusually different populations.
- Test plausible within-study correlations in dependence models.
- Examine whether unpublished or very small studies drive the conclusion.
Do not remove an outlying study only because it changes the pooled effect. Investigate data extraction, eligibility, design, population, and influence. If it remains eligible, show analyses with and without it and explain what the difference means.
Present results so readers can audit them
| Result element | Minimum reporting | Interpretation question |
|---|---|---|
| Study flow | Records identified, screened, excluded, and included | Could eligible evidence have been missed? |
| Study characteristics | Population, design, measures, timing, and setting | Are the studies sufficiently comparable? |
| Forest plot | Study effects, intervals, weights, and pooled estimate | Which studies drive the result? |
| Heterogeneity | Q, I-squared, tau-squared, and prediction interval when suitable | How much do true effects vary? |
| Risk of bias | Domain judgements with support | Could flaws systematically distort the estimate? |
| Sensitivity results | Prespecified alternative analyses | Does the conclusion depend on one decision? |
A forest plot should show each study’s effect estimate and confidence interval, the effect direction, study weight, and pooled result. Label scales and groups clearly. Do not interpret overlap between individual confidence intervals as a formal test of differences.
Report exact model choices, estimator, software, package, version, code, and any non-default options. Provide extraction data and reproducible scripts when ethics, copyright, and institutional rules permit. The site’s results-section guide explains how to organise statistical findings without repeating tables in prose.
Follow PRISMA and psychology reporting standards
PRISMA 2020 provides a checklist and expanded guidance for reporting systematic reviews. Its flow diagram records the movement from identification to inclusion. PRISMA improves completeness of reporting but does not itself certify methodological quality.
Psychology dissertations should also follow applicable institutional and APA meta-analysis reporting expectations. Report the research question, eligibility, search, coding, effect calculations, dependence decisions, model, heterogeneity, bias assessment, additional analyses, limitations, data availability, funding, and conflicts. Use the checklist during planning, not only after writing.
Common meta-analysis mistakes
- Pooling because studies report numbers: statistical convertibility does not establish conceptual compatibility.
- Treating all effects as independent: multiple outcomes from one sample require an explicit dependence strategy.
- Selecting outcomes after seeing results: prespecify a hierarchy or model all eligible dependent effects appropriately.
- Using I-squared as a quality score: it does not measure bias or the absolute importance of heterogeneity.
- Equating funnel asymmetry with publication bias: several mechanisms can create asymmetry.
- Running too many moderators: sparse meta-regression encourages unstable, chance findings.
- Reporting only the pooled p value: effect magnitude, interval, heterogeneity, prediction, and bias determine meaning.
- Ignoring study quality: precise synthesis of biased studies can produce a precise but misleading answer.
Frequently asked questions
How many studies are needed for a meta-analysis?
Two compatible studies can technically be combined, but a small set provides limited information about heterogeneity, publication bias, and moderator effects. The appropriate analysis depends on study precision and assumptions. State the limitations clearly and avoid elaborate secondary analyses with sparse evidence.
Should I always use a random-effects model?
No. Choose the model from the inferential question and expected effect structure, not from a heterogeneity p value. Random-effects models are common in psychology because true effects may vary, but they require careful estimation and interpretation, especially with few studies.
Can I combine different psychological scales?
Yes, if they measure the same underlying construct sufficiently well and the standardised mean difference is appropriate. Confirm direction, construct validity, reliability, timing, and population comparability. Standardisation does not repair fundamentally different constructs.
What software can I use?
R packages such as metafor, meta, robumeta, and clubSandwich support many common and advanced models. Stata, Comprehensive Meta-Analysis, RevMan, and other programs may also be suitable. Choose software that implements the prespecified method transparently, then report the version and settings.
What if studies are too heterogeneous to pool?
Do not force a summary. Reconsider eligibility, form defensible subgroups, or conduct a structured synthesis without meta-analysis. Explain which differences prevented pooling and how the evidence was compared. This is a methodological decision, not a failed project.
Conclusion
A strong psychology dissertation meta-analysis begins with a precise estimand and a transparent review protocol. It uses comparable effect sizes, respects dependence, chooses a defensible model, quantifies heterogeneity, examines bias, and tests important assumptions. The pooled estimate is one part of the answer. Its credibility depends on the studies, decisions, uncertainty, and scope surrounding it. The power-analysis guide explains why sparse evidence limits precision and secondary analyses.
If you need support planning a meta-analytic dissertation, Psychology Dissertation Help can assist with ethical question refinement, protocol structure, extraction design, analysis planning, and transparent reporting. Use any support to strengthen your own scholarly decisions and comply with your university’s academic-integrity, supervision, and authorship rules.


