

Psychology dissertation observational study projects turn visible behaviour into analysable evidence through a predefined, ethical, and reproducible recording plan. They are valuable when a research question concerns what people do, when they do it, or how interaction unfolds, rather than only what participants remember or report.
Observation is not simply watching. A defensible dissertation specifies the setting, behavioural units, sampling rules, coding decisions, observer training, reliability checks, and analysis before interpreting any pattern. This guide shows how to make those choices align.
What a Psychology Dissertation Observational Study means in psychology
In direct systematic observation, a researcher records defined actions, states, events, or interaction features as they occur live or in a recording. Examples include turn-taking during peer collaboration, helping behaviour in a public setting, caregiver responsiveness, classroom on-task behaviour, or facial and verbal responses during a structured task.
Observation can reduce dependence on memory and self-presentation, but it does not produce neutral facts automatically. The setting changes what can occur, a codebook determines what becomes data, and observers make classifications. A rigorous design makes those influences visible and manageable.
| Method | Primary evidence | Best suited question | Main limitation to manage |
|---|---|---|---|
| Structured observation | Predefined coded behaviours | How often, how long, or in what sequence does behaviour occur? | Reactivity and coding error |
| Ethnography | Fieldnotes, participation, and cultural interpretation | How do members understand practices in context? | Reflexivity and prolonged access |
| Experiment | Outcomes following manipulated conditions | Does an intervention or condition cause a difference? | Internal validity and generalisability |
| Self-report study | Questionnaire or interview responses | What do people perceive, remember, or believe? | Recall and response biases |
A structured observation therefore has a different search intent and methodological purpose from a psychology dissertation ethnography or experimental design. It may be naturalistic, where behaviour is recorded in an ordinary setting, or controlled, where every participant completes the same task without random assignment or manipulation.
Table of Contents
Start with an observable research question
A question must identify a behaviour, population, context, and comparison or relationship. “How does anxiety affect communication?” is too broad for direct coding. “Is the proportion of speaking turns preceded by hesitation associated with self-reported social anxiety during a five-minute paired discussion?” specifies observable units and a separate measure.
A descriptive question might ask how frequently collaborative statements occur. A comparative question might contrast two naturally occurring groups. A relational question could test whether observed caregiver prompts covary with child task persistence. Because the researcher does not manipulate exposure, causal language is generally unjustified. State whether the design is descriptive, comparative, or associational.
Define the unit of observation and unit of analysis
The unit of observation is what receives a code, such as a five-second interval, speaking turn, gesture, person, dyad, or session. The unit of analysis is the independent unit represented in the statistical model. Ten coded intervals from each of 30 participants do not automatically create 300 independent cases. Repeated observations are clustered within people, and dyadic observations may also be interdependent.
Write both units explicitly. This prevents pseudo-replication, guides the sampling plan, and clarifies whether analysis needs aggregation, repeated-measures methods, or a multilevel model.
Choose the observation setting and researcher role
Naturalistic observation can offer strong ecological relevance because behaviour occurs in a familiar setting. It also brings less control over noise, visibility, competing events, and unequal opportunities to display a target action. Controlled observation standardises the task, materials, duration, and instructions, which aids comparison but may make behaviour less typical.
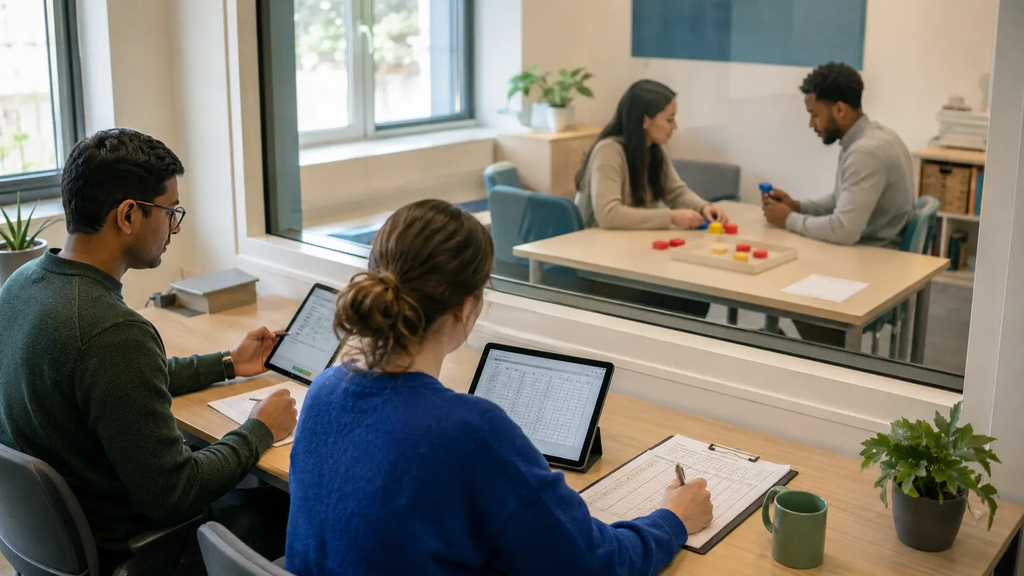
Non-participant observers remain outside the activity. Participant observers join it, a role more common in qualitative work and requiring close reflexive attention. Disclosed observation is usually the ethical default in dissertation research. Covert observation requires a compelling justification, formal ethics approval, and careful assessment of privacy, consent, risk, and debriefing under local rules. Public accessibility alone does not make unrestricted recording ethically acceptable.
Operationalise behaviour before collecting data
An operational definition tells a trained observer exactly when a code starts, when it ends, and what does not qualify. Replace “aggression” with actions that can be seen or heard, such as an attempt to strike another person, an object thrown toward someone, or a spoken threat. Separate behaviour from inferred intention unless intention is itself assessed by another method.
Good definitions are mutually exclusive when a single code is required and collectively sufficient for the question. Include borderline cases, non-examples, an “uncodable” option, and a rule for simultaneous behaviours. The coding scheme should be detailed enough for consistency without fragmenting behaviour into categories too rare to analyse.
A peer-reviewed guide to developing behavioural coding schemes recommends iterative refinement and shows that coding can take several times the duration of the original observation. Budgeting for that workload is part of feasibility, not an afterthought.
Build a practical codebook
For every code, record its label, conceptual meaning, observable definition, inclusion and exclusion rules, start and stop rule, level of measurement, examples, and conflict rule. Add a version number and revision log. If definitions change after the pilot, preserve the old version and recode affected pilot material rather than mixing incompatible rules.
For example, “supportive response” might mean a verbal acknowledgement, offer of help, or validating statement made within ten seconds of a partner expressing difficulty. Silence, topic change, and problem solving without acknowledgement could be specified as non-examples. The ten-second boundary is contestable, but it makes classification testable.
Select a behavioural sampling strategy
It is rarely feasible to record every behaviour from every person throughout the whole setting. Behavioural sampling determines which moments or events enter the dataset. Choose it from the research question and expected base rate, then keep the rule constant across participants.
| Strategy | How it works | Useful for | Key caution |
|---|---|---|---|
| Continuous recording | Code every target event and its timing | Sequences, frequency, and duration | High observer and coding burden |
| Event sampling | Record each occurrence of a specified event | Discrete or relatively rare actions | Needs a denominator or exposure time |
| Interval recording | Code whether behaviour occurs within fixed periods | States across a session | Can distort frequency or duration |
| Momentary time sampling | Code behaviour at predetermined instants | Estimating time allocation | Brief events may be missed |
| Focal sampling | Observe one selected person for a defined period | Individual behaviour in groups | Selection order must be balanced |
For event sampling, report both count and opportunity. Five interruptions in five minutes is different from five interruptions in twenty minutes. Rates may use minutes observed, speaking turns, requests received, or another theoretically meaningful denominator. A methodological review of observational coding explains how interval methods answer different questions from event-based coding and should not be treated as interchangeable.
Sample occasions across times, days, tasks, or locations when those contexts could influence behaviour. A convenience window may systematically omit relevant variation. Record exposure time and any interruption, obstruction, equipment failure, or participant absence so that missing observation is distinguishable from absence of behaviour.
Pilot the full observation process
A pilot study should test recruitment, consent, camera placement, audibility, observation length, code definitions, category frequencies, observer workload, data export, and planned analysis. Use material similar to the main study but keep pilot participants outside the final dataset unless the protocol and approval permit inclusion.
Look for codes that observers confuse, events that occur too rarely, categories that overlap, and contexts where the target behaviour cannot be seen. Revise before the main sample. Do not repeatedly adapt the scheme after looking at substantive results, because data-dependent definitions can favour an emerging story.
Train observers and control drift
Training should combine codebook study, worked examples, independent practice, comparison against a criterion set, discussion of discrepancies, and a prespecified performance threshold. Observers need practice on easy and ambiguous cases. When possible, keep them unaware of participant group, hypothesis, or questionnaire scores to reduce expectancy effects.
Agreement can deteriorate as observers develop personal shortcuts. Insert periodic calibration cases and assess a randomly selected subset throughout data collection, not only at the beginning. If drift occurs, document retraining and decide prospectively whether earlier sessions require recoding.
Assess interobserver agreement properly
Interobserver evidence asks whether the recorded data depend excessively on who coded them. Double-code a meaningful, distributed subset of sessions selected independently of apparent difficulty or expected result. Report how the subset was chosen, how many observations and participants it covered, whether coders were independent, and whether disagreements were resolved before analysis.
Raw percentage agreement is intuitive but includes agreement expected by chance and can look high when one category dominates. Cohen’s kappa is commonly used for two observers coding nominal categories. Weighted kappa can suit ordered categories when the weighting rule is justified. For continuous ratings or durations, an intraclass correlation coefficient may be suitable, but the model, type, and whether the target is consistency or absolute agreement must be stated.
Hallgren’s overview of reliability for observational data explains that the statistic should match the data and design. McHugh’s kappa review discusses chance-corrected agreement, while Koo and Li’s ICC reporting guideline shows why naming the selected ICC form matters. Avoid presenting a single universal threshold as proof that a code is valid. Give the estimate, confidence interval where feasible, category prevalence, and substantive consequences of disagreement.
Reduce reactivity and observer bias
People may change behaviour because they know they are observed. This is reactivity, not a reason to conceal observation automatically. Use a familiarisation period, unobtrusive but disclosed equipment, identical instructions, adequate session length, and the same observer position across participants. Record whether participants interact with the camera or observer, and consider a sensitivity analysis excluding an initial acclimatisation period if that decision was planned.
Observer bias can arise when expectations affect classification. Strong definitions, masked coding, randomised coding order, independent double-coding, and automated timestamps can help. Software can improve consistency of playback and data entry, but it does not validate categories. A primer on observational measurement treats reactivity, observer reliability, and measurement design as linked concerns.
Plan ethics, privacy, and data security
Observation can capture identifiable faces, voices, locations, bystanders, relationships, and sensitive events. The consent materials should explain what is observed, whether recording occurs, who will access raw material, how extracts might be used, how long files will be retained, and whether participants can pause or withdraw according to the approved procedure.
The APA Ethics Code emphasises protecting confidential information and obtaining consent for voice or image recording in research, subject to defined exceptions. Apply the rules of the institution and jurisdiction governing the project, because legal and ethics requirements differ globally. Seek approval before recruitment and submit amendments before changing the setting, recording method, or consent process.
Store recordings in approved encrypted systems, separate identity keys from coded data, restrict access, and define deletion dates. Do not place identifiable recordings in consumer tools without institutional approval. For group settings, explain that one person’s withdrawal may affect footage containing others. Plan how bystanders, safeguarding disclosures, and incidental sensitive information will be handled.
Create an analysis plan that matches the codes
Begin with a data dictionary and a row structure. One row might represent an event, interval, participant-session, or dyad-session. Include participant and session identifiers, observation duration, coder, codebook version, contextual variables, visibility, and missingness reason. Preserve raw coded records and derive summaries through documented steps.
| Observed outcome | Possible summary | Analysis issue |
|---|---|---|
| Event count | Count or rate per exposure time | Unequal observation time and overdispersion |
| Duration | Seconds or proportion of visible time | Skew and bounded proportions |
| Binary interval code | Proportion of intervals | Intervals clustered within sessions |
| Sequence | Transition probability or lagged association | Temporal dependence and sparse transitions |
| Global rating | Ordinal or continuous score | Scale properties and coder reliability |
Use descriptive statistics before modelling. Show distributions, exposure times, zeros, missing observations, and values by context. Match the inferential model to the outcome and dependence structure. Count models may suit event frequencies, while multilevel models can represent observations nested within sessions and participants. A proportion formed from a small and varying number of opportunities needs more care than an ordinary continuous score.
Predefine covariates from theory rather than selecting them only because they change significance. Distinguish confounders, contextual predictors, and variables that may be consequences of the behaviour. If the sample is modest, simplify the question and model instead of fitting more parameters than the data can support.
Handle missing and unobservable periods transparently
A zero means the behaviour was observable but did not occur. Missing means it was not validly assessed. Camera obstruction, inaudible speech, a participant leaving the setting, and corrupted files need explicit codes. Describe the amount and reasons, compare missingness across groups where relevant, and justify exclusions. The site’s guide to missing data can support a fuller plan.
Report the study so another researcher can understand it
The methods chapter should identify the design, setting, participants, observation schedule, researcher role, apparatus, behavioural sampling, operational definitions, codebook development, training, masking, agreement subset, reliability statistics, ethics, and analysis. Report deviations from the protocol and the reasons for them.
In results, give participant and observation flow, number and duration of sessions, visibility or missingness, code frequencies, reliability estimates, descriptive results, model estimates with uncertainty, and sensitivity analyses. Use anonymised examples only when consent and approval permit them. Do not imply that an association demonstrates causation.
The STROBE statement is relevant when a dissertation uses a cohort, case-control, or cross-sectional observational design. It is a reporting checklist, not a design-quality score, and it does not replace behaviour-specific coding detail. For broader psychology reporting, also follow the institution’s required journal article reporting standards.
Common mistakes and practical repairs
- Vague constructs: replace inferred traits with observable indicators and acknowledge what the codes cannot establish.
- No behavioural denominator: report events per minute, opportunity, turn, or another justified exposure.
- Reliability checked only in training: double-code a distributed subset from the main study.
- Inflated sample size: model or aggregate repeated observations without treating intervals as independent participants.
- Changing rules silently: version the codebook, document revisions, and recode affected material consistently.
- Confusing zero with missing: add visibility and reason fields before data collection.
- Overclaiming causality: describe observed differences or associations within the sampled settings.
- Weak privacy planning: obtain approval for recording, minimise identifiable data, restrict access, and set deletion rules.
Frequently asked questions
Is an observational study qualitative or quantitative?
It can be either. Systematic behavioural coding usually produces quantitative counts, durations, ratings, or sequences. Field observation may instead generate qualitative notes and interpretations. Some projects integrate both, but each strand needs a clear analysis plan.
How many observation sessions are needed?
There is no universal number. It depends on the unit of analysis, expected variability and event rate, clustering, planned comparison, precision target, attrition, and feasible coding load. Justify the sample using the intended analysis and pilot information, not an arbitrary session count.
Must every session be coded by two observers?
Not necessarily. Many studies independently double-code a prespecified, randomly distributed subset. The proportion must be sufficient to estimate agreement for important codes and detect drift. Explain the selection rule and keep adjudicated data separate from the independent reliability calculation.
Can one researcher collect and code all observations?
One person can code the full dataset, but an independent second coder is normally needed for interobserver evidence. If no second coder is feasible, state the limitation and strengthen definitions, masking, audit trails, and repeat-coding checks without mislabelling intrarater consistency as interobserver reliability.
Can observation show cause and effect?
Usually not by itself. It can describe behaviour and estimate associations in context. Strong causal conclusions require a design and assumptions that address alternative explanations, temporal ordering, confounding, selection, and measurement bias.
Should video be retained after the dissertation?
Follow the approved protocol, consent language, institutional policy, funder requirements, and applicable law. Retain only what is necessary, protect it appropriately, and delete identifiable recordings on the authorised schedule.
Conclusion
A rigorous psychology dissertation observational study connects a focused question to observable definitions, a defensible sampling plan, trained coding, reliability evidence, ethical recording, and analysis that respects exposure and clustering. Its credibility comes from transparent decisions rather than the apparent immediacy of watching behaviour.
If you want ethical dissertation support, use feedback to strengthen your own design, codebook, analysis plan, and reporting. Preserve authorship, obtain supervisor and ethics approval, and never outsource participant contact, data fabrication, or decisions that require access to confidential research records.


